Explore papers
Filter by research area, year and venue. Every filter is in the address bar, so you can share a view as a link.
 Deepfakes & multimodalDetection methods
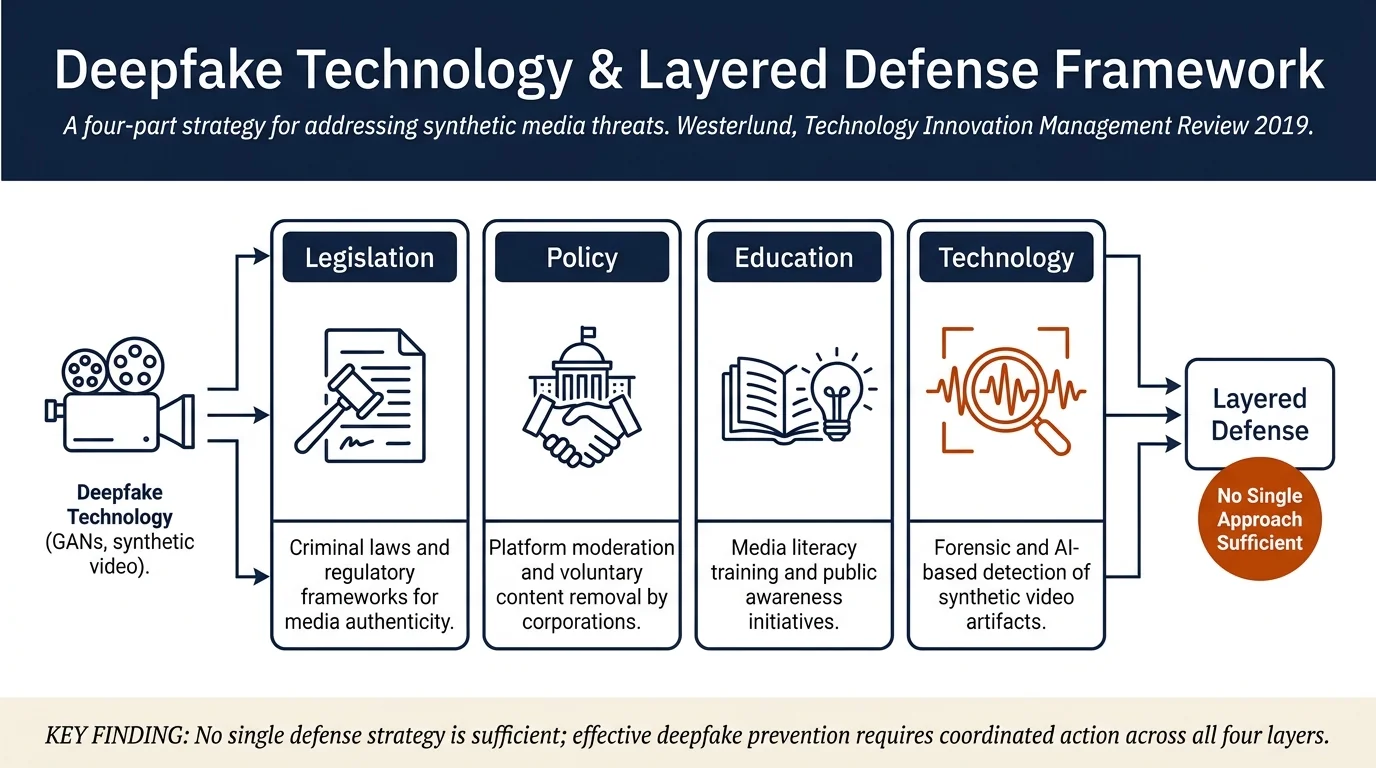
The Emergence of Deepfake Technology: A ReviewThis review analyzes 84 news articles about deepfakes to synthesize understanding of synthetic video technology, its applications, threats, and countermeasures. Deepfakes—hyper-realistic videos created using AI (primarily GANs)—lower the barrier to video forgery and represent a significant threat to trust, elections, and security.
 Deepfakes & multimodalDetection methods
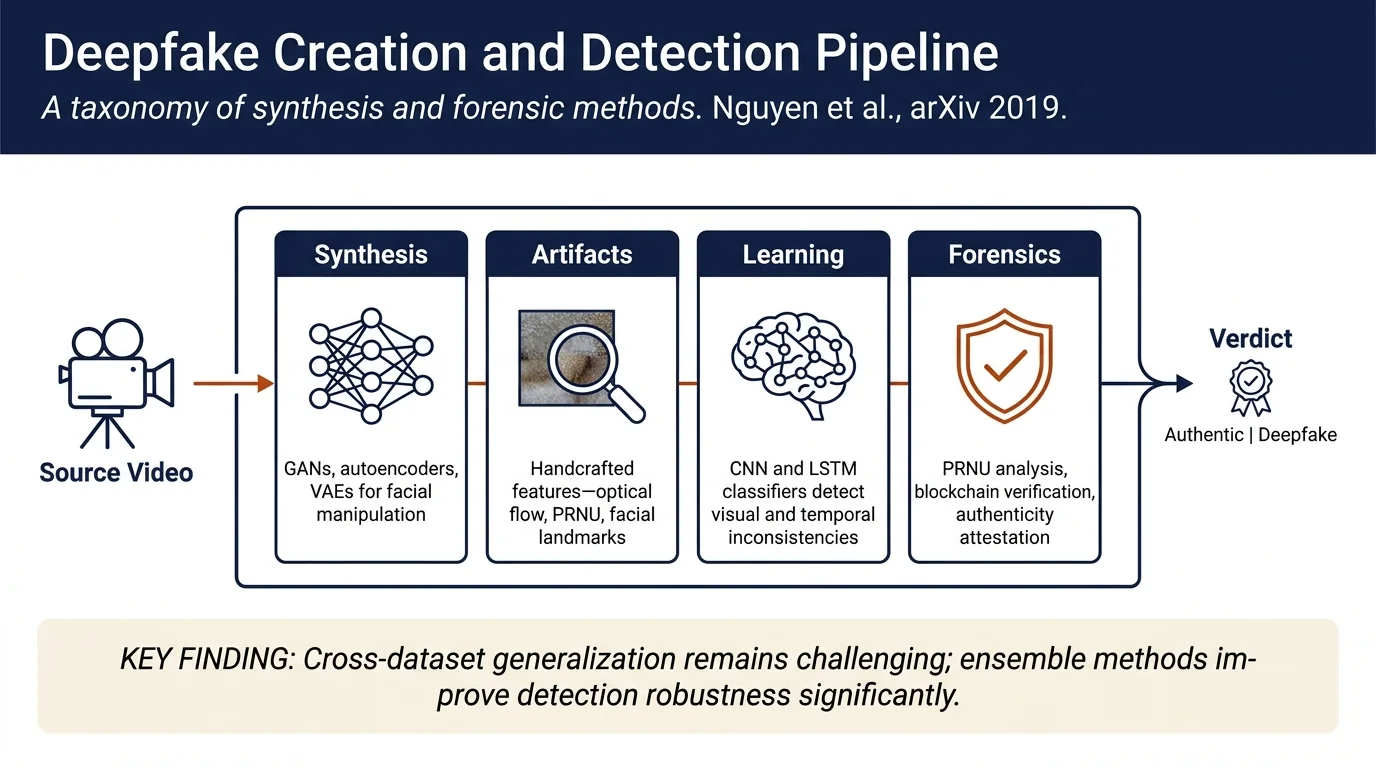
Deep Learning for Deepfakes Creation and Detection: A SurveyComprehensive survey of deep learning methods for creating and detecting deepfakes, covering face-swapping and lip-syncing generation techniques (GANs, autoencoders, encoder-decoder pairs), detection approaches (visual artifacts, temporal features, forensics), and challenges in cross-dataset generalization. The paper discusses…
 Spread & networksPlatforms, policy & society
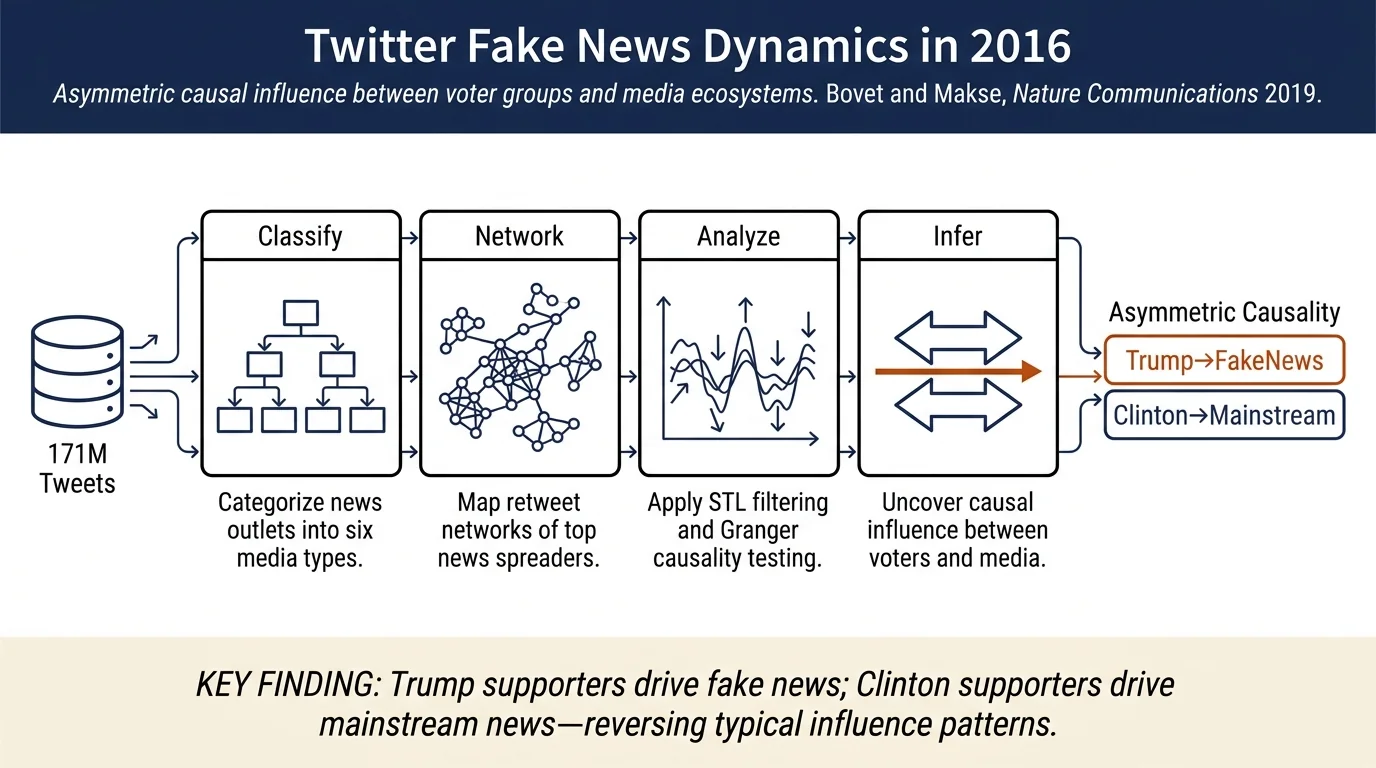
Influence of fake news in Twitter during the 2016 US presidential electionUsing 171 million tweets from the five months preceding the 2016 U.S. election, this study found that 25% of news-sharing tweets contained fake or extremely biased content. Network analysis revealed distinct clusters of fake, biased, and mainstream news spreaders.
 LLMs & generative AIDetection methods
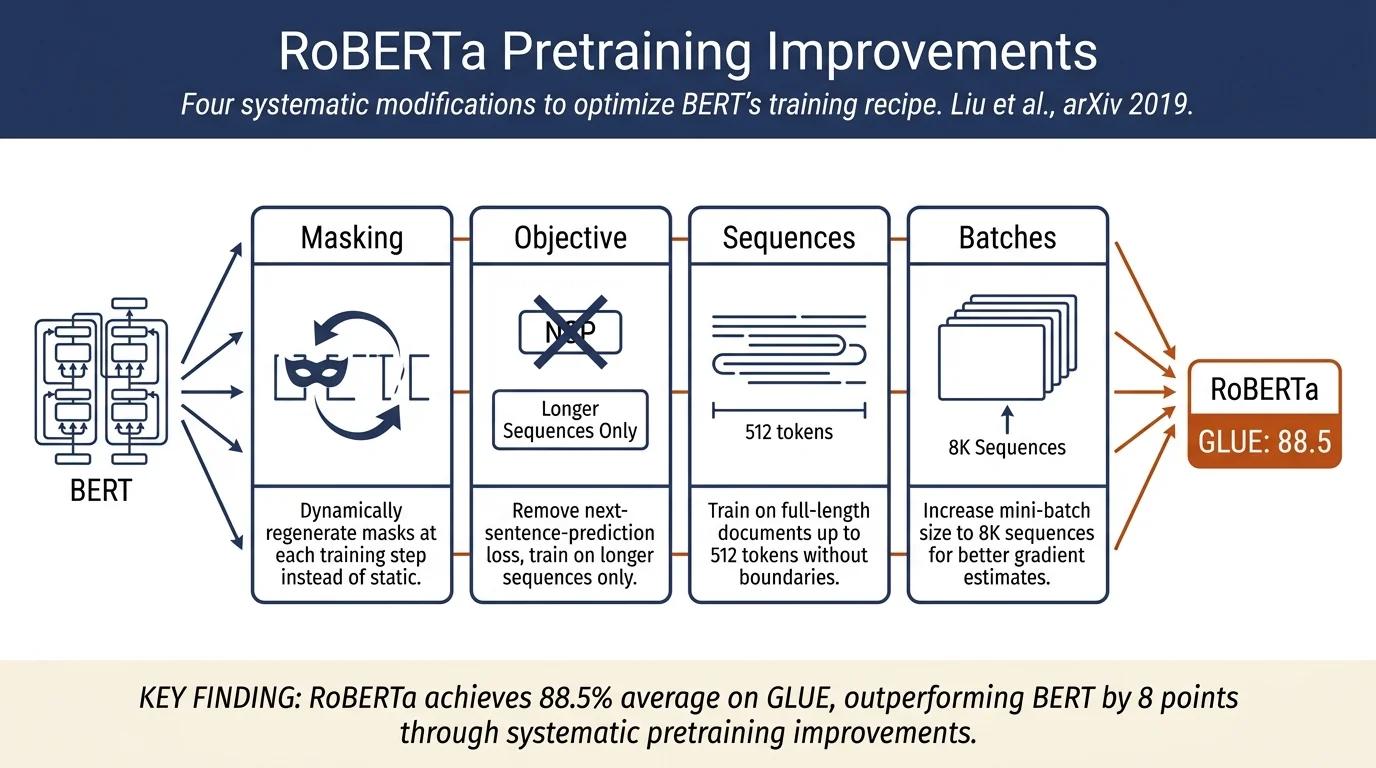
RoBERTa: A Robustly Optimized BERT Pretraining ApproachA replication and improvement study of BERT pretraining showing that BERT was significantly undertrained. RoBERTa introduces four key improvements—training longer with larger batches and more data, removing the next-sentence-prediction objective, training on longer sequences, and dynamically masking tokens—to achieve state-of-the-art…
 Platforms, policy & society
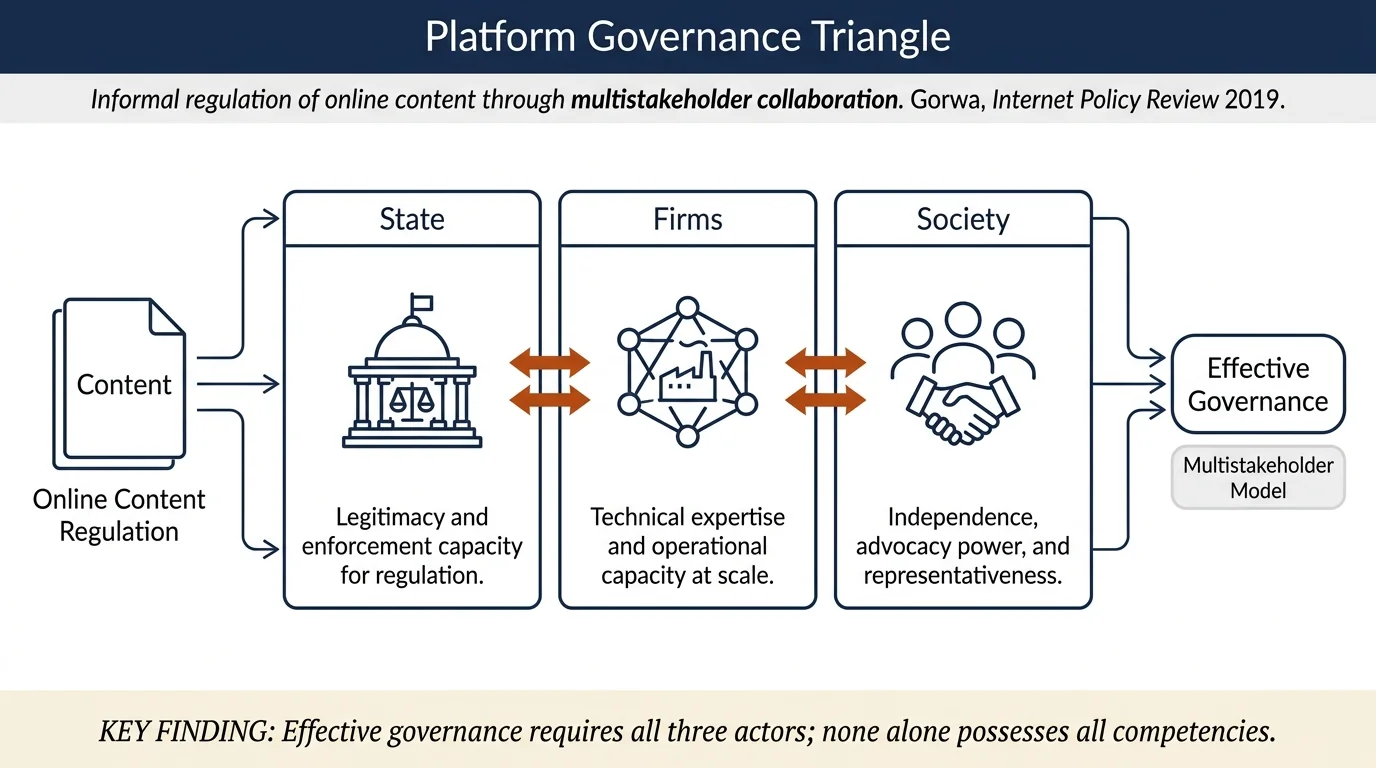
The platform governance triangle: conceptualising the informal regulation of online contentThis paper applies Abbott and Snidal's "governance triangle" framework to analyze how state actors, technology firms, and civil society organizations informally regulate online content through voluntary standards, codes of conduct, and multistakeholder initiatives. The analysis maps the European platform governance landscape, showing how…
 Detection methodsDatasets & evaluation
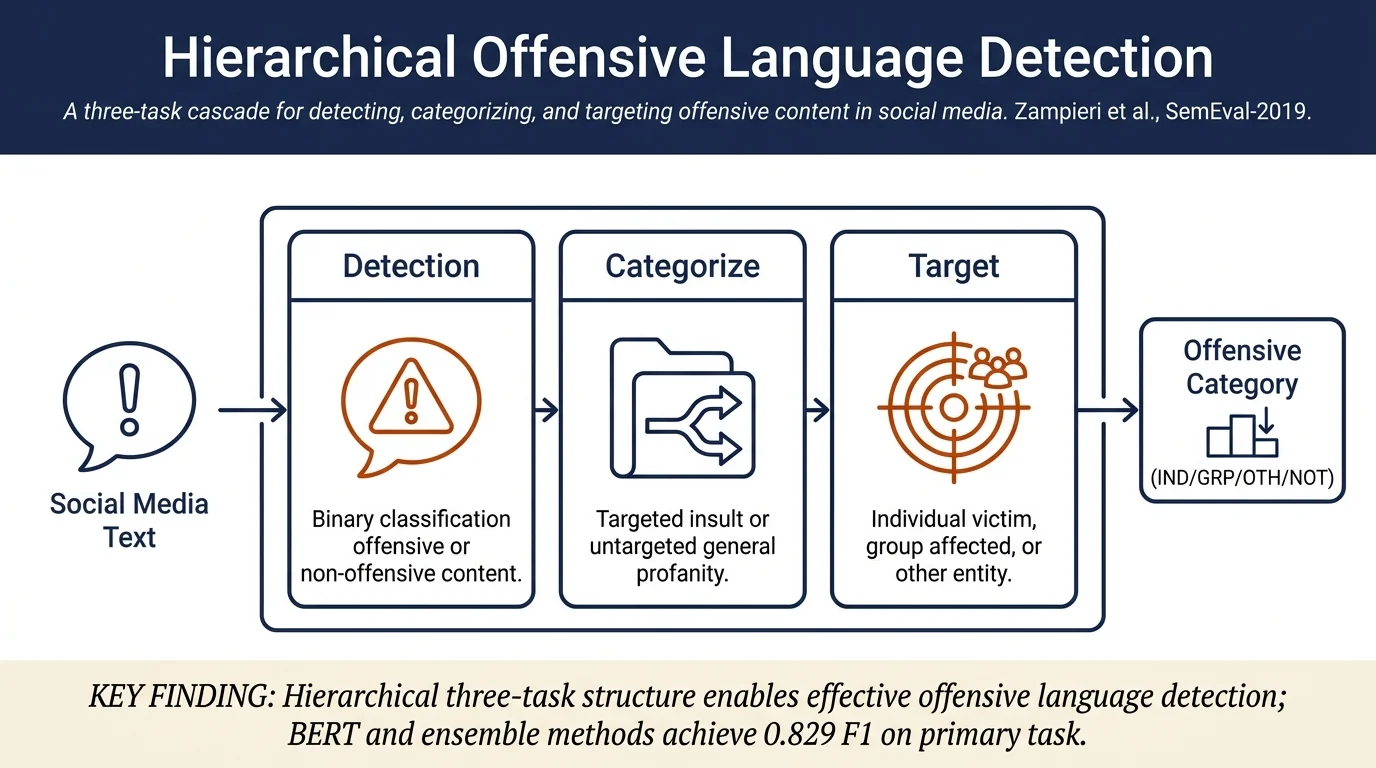
SemEval-2019 Task 6: Identifying and Categorizing Offensive Language in Social MediaSemEval-2019 Task 6 reports on a shared task competition for identifying and categorizing offensive language in social media using the OLID dataset. Approximately 800 teams registered and 115 submitted results across three sub-tasks: offensive language detection (104 teams), offense type categorization (71 teams), and offense target…
 Datasets & evaluationDetection methods
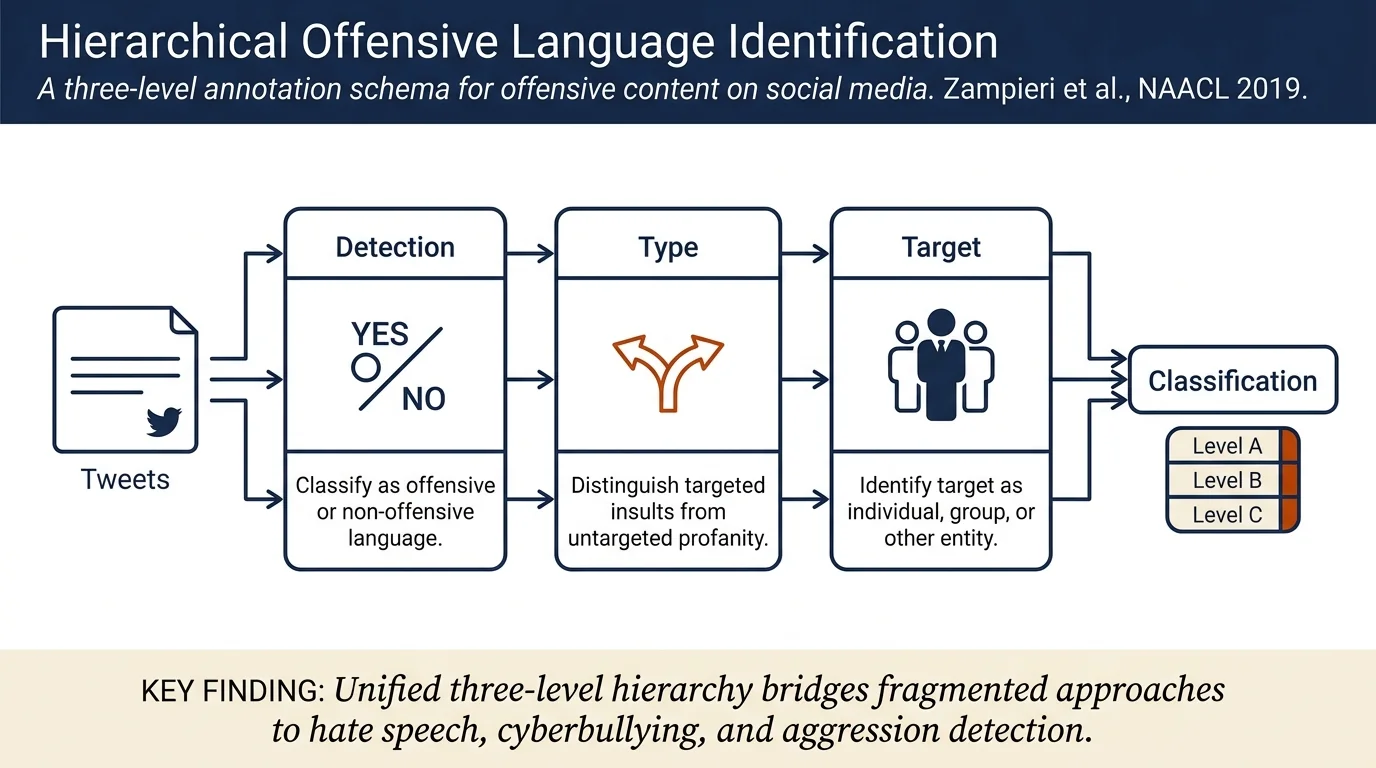
Predicting the Type and Target of Offensive Posts in Social MediaThis paper introduces OLID (Offensive Language Identification Dataset), a large-scale dataset of 14,100 English tweets annotated with a three-level hierarchical schema for detecting offensive content. The hierarchy distinguishes offensive from non-offensive posts (Level A), categorizes offense type as targeted insults or untargeted…
 Detection methodsLLMs & generative AI
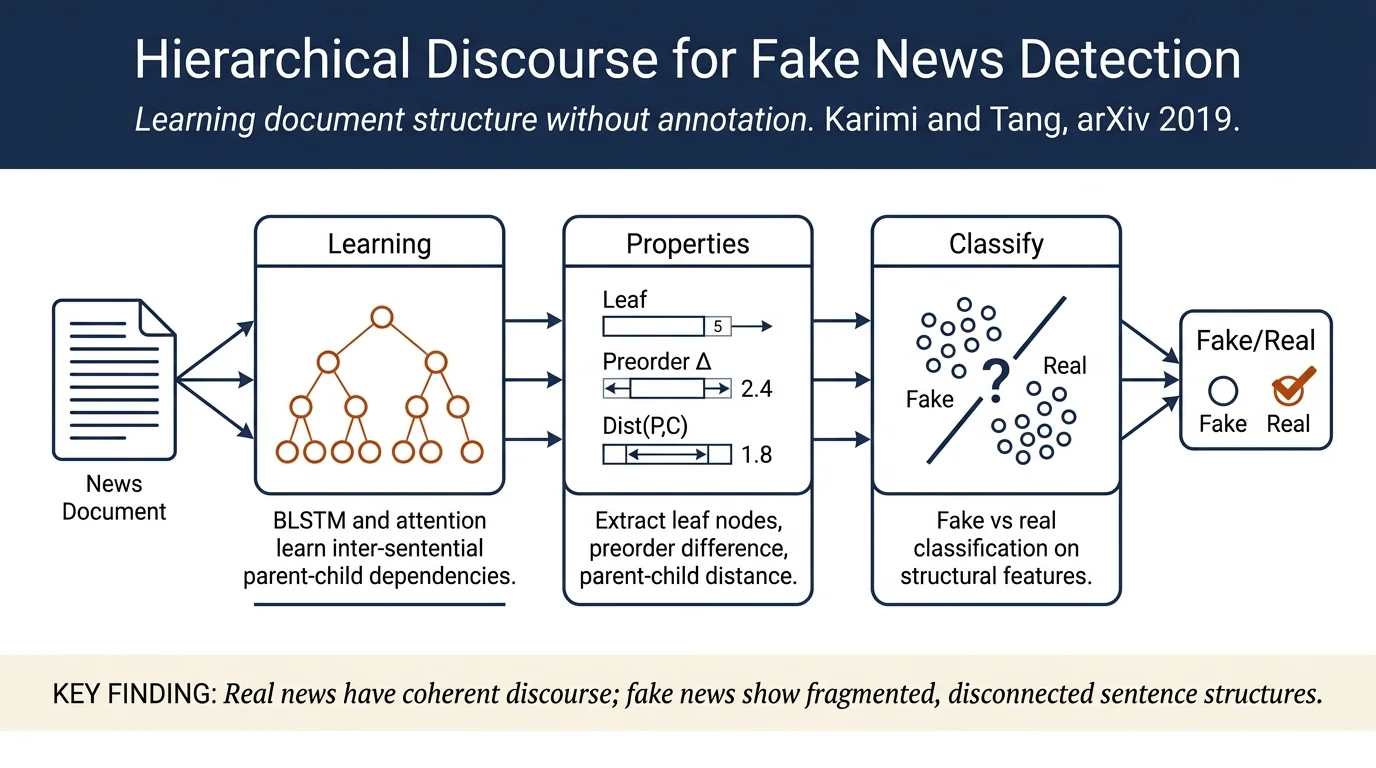
Learning Hierarchical Discourse-level Structure for Fake News DetectionProposes HDSF, a framework that learns hierarchical discourse-level structure (dependency trees of sentences) for fake news detection without annotated corpora. Identifies three structure-related properties that distinguish fake from real news and shows HDSF achieves 82.19% accuracy, outperforming linguistic baselines.
 Spread & networksPlatforms, policy & society
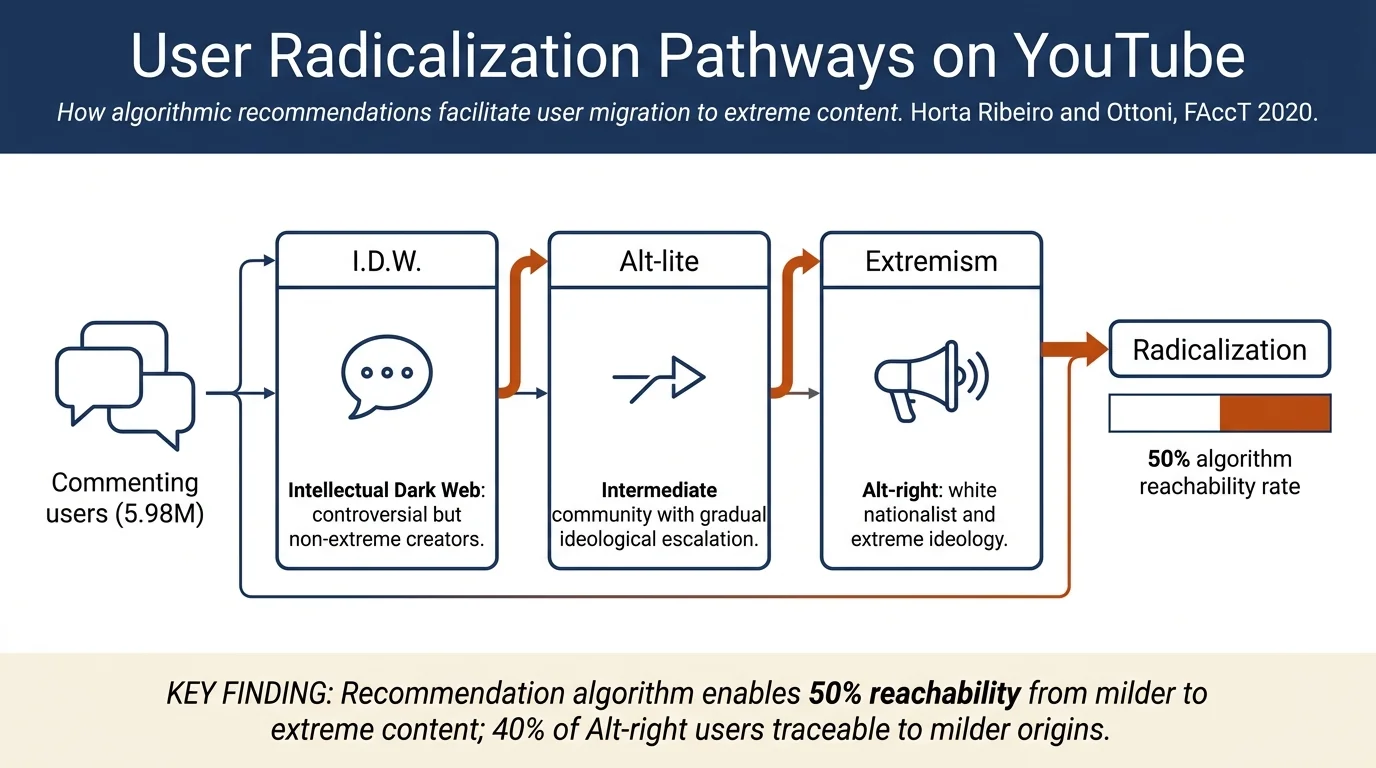
Auditing Radicalization Pathways on YouTubeFirst large-scale quantitative audit of user radicalization on YouTube. The authors tracked 349 channels across three ideological communities (Intellectual Dark Web, Alt-lite, Alt-right) and found strong evidence that users systematically migrate toward more extreme content.
 Fact-checking & verificationDatasets & evaluation
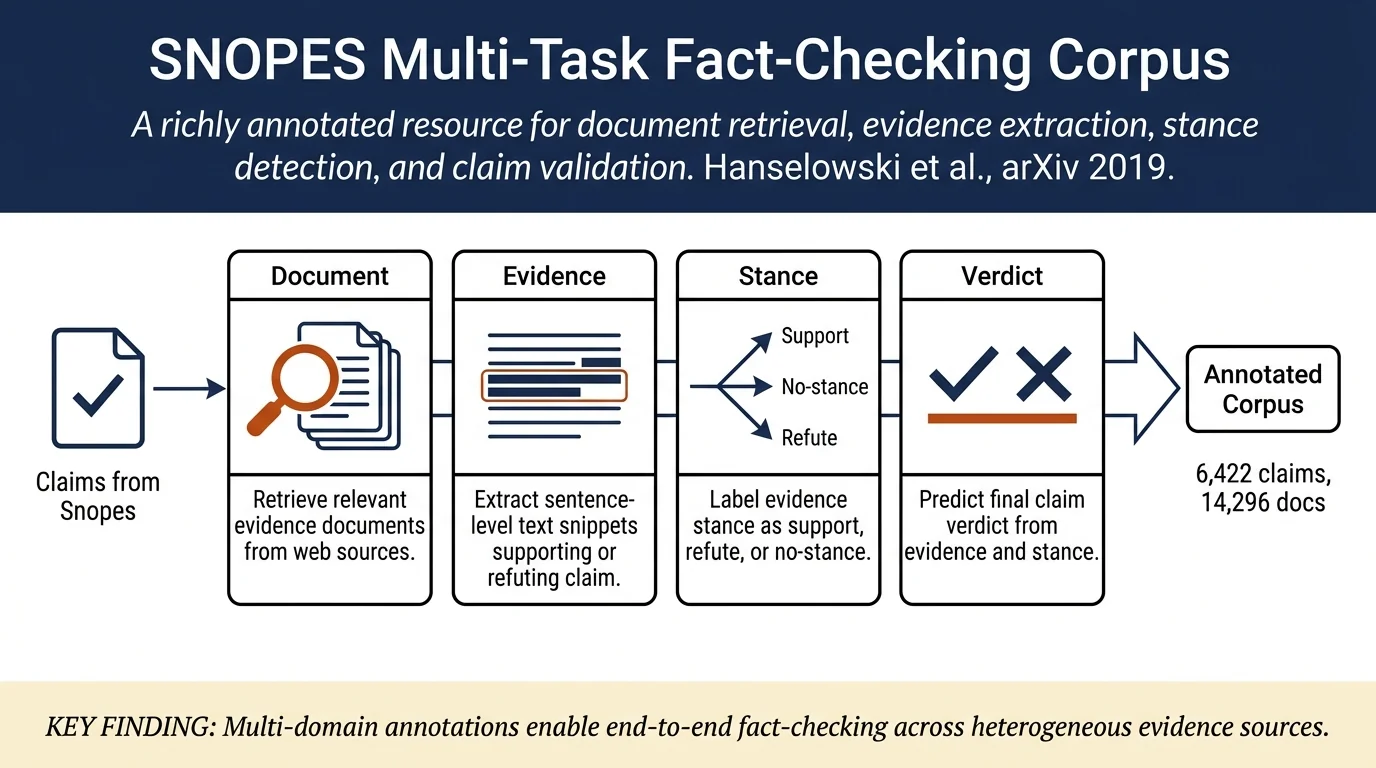
A Richly Annotated Corpus for Different Tasks in Automated Fact-CheckingThe paper introduces SNOPES, a large-scale fact-checking corpus with 6,422 validated claims and 14,296 documents covering multiple domains (news, social media, blogs). Each claim is annotated with evidence text snippets, evidence stance (support/refute/no stance), and verdicts, enabling training of models for four core fact-checking…
 Fact-checking & verificationDatasets & evaluation
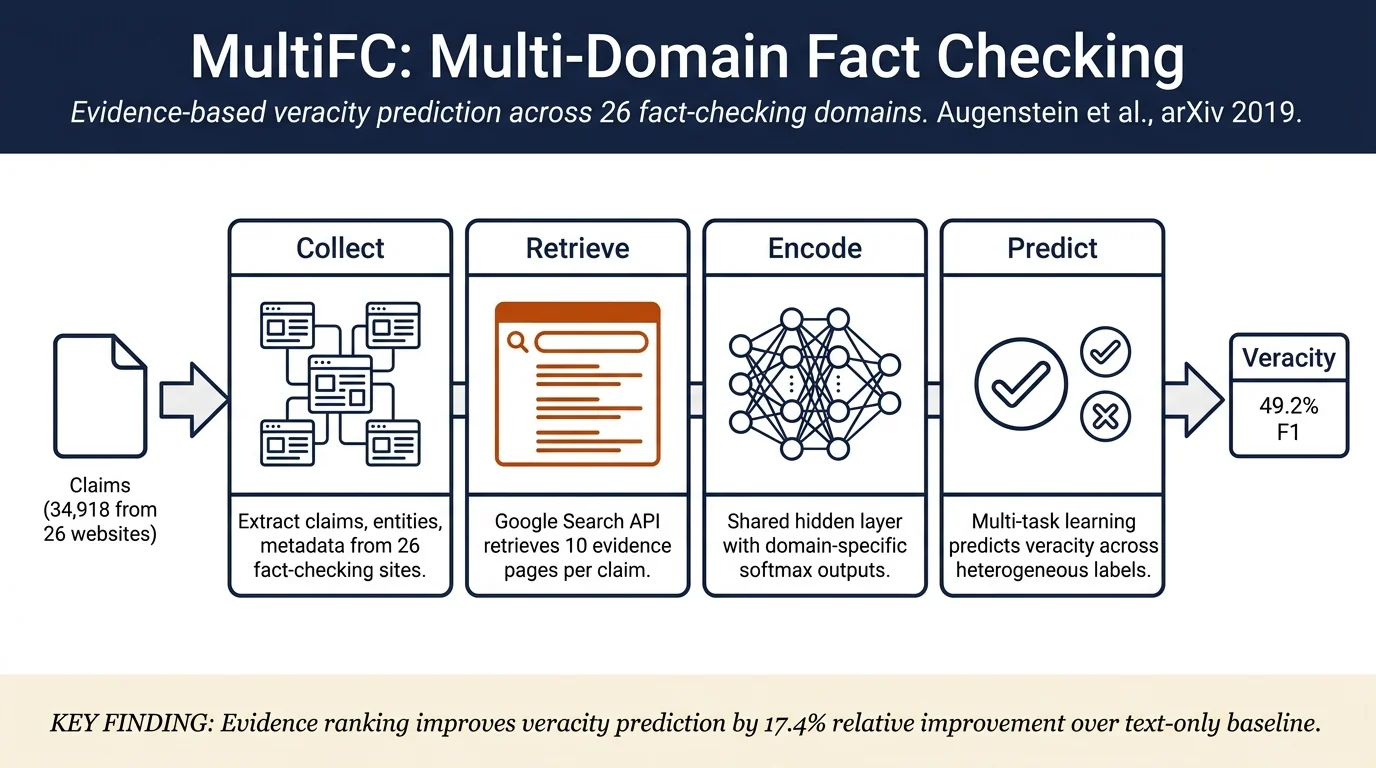
MultiFC: A Real-World Multi-Domain Dataset for Evidence-Based Fact Checking of ClaimsMultiFC is the largest publicly available real-world dataset of naturally occurring factual claims (34,918 claims) collected from 26 fact-checking websites, with rich metadata, evidence pages retrieved via Google Search, and entity linking to Wikipedia. The paper demonstrates that evidence ranking combined with veracity prediction…
 Bots & coordinated campaignsDeepfakes & multimodal
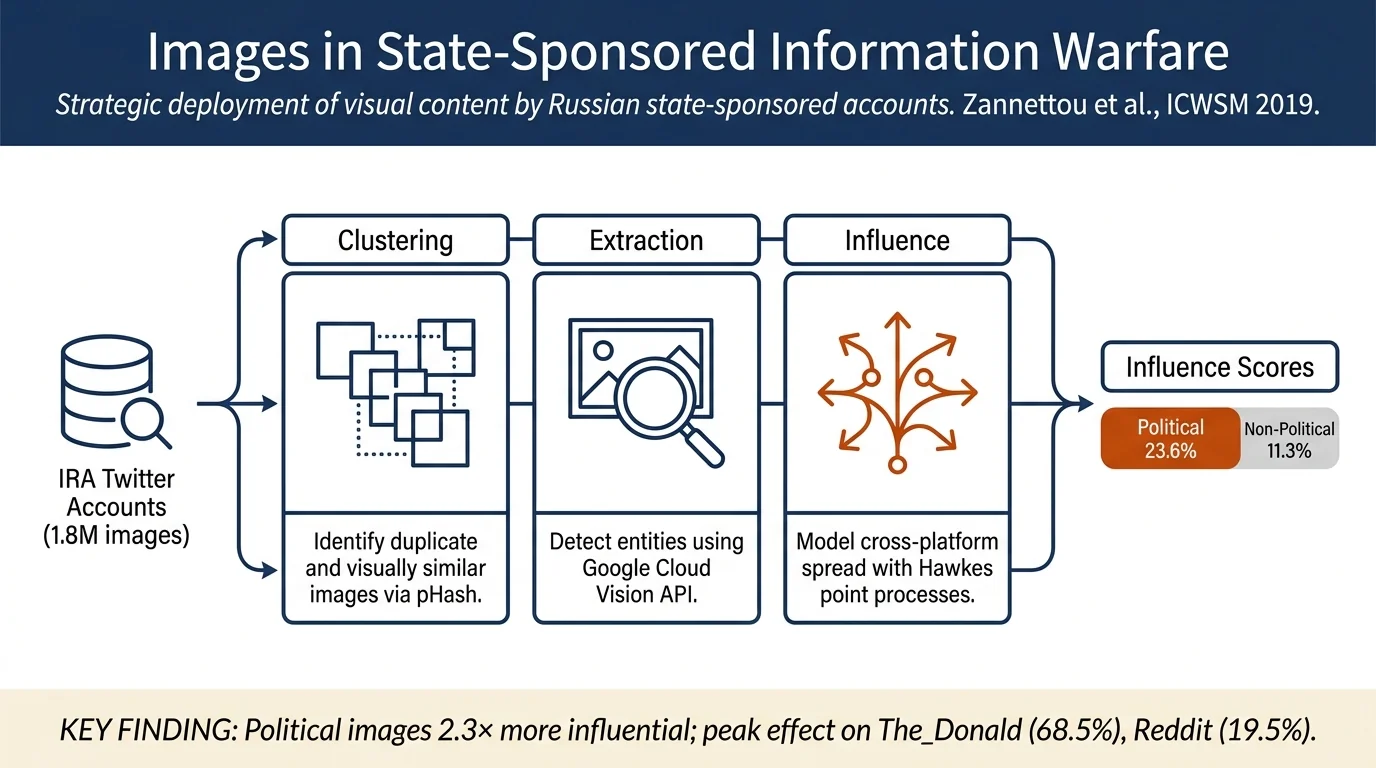
Characterizing the Use of Images in State-Sponsored Information Warfare Operations by Russian Trolls on TwitterLarge-scale analysis of 1.8M images posted by ~3.6K Russian state-sponsored Twitter accounts (IRA-controlled). Russian trolls strategically deployed images and memes to maximize political influence, with political imagery 2+ times more effective than general content.
 Bots & coordinated campaignsDatasets & evaluation
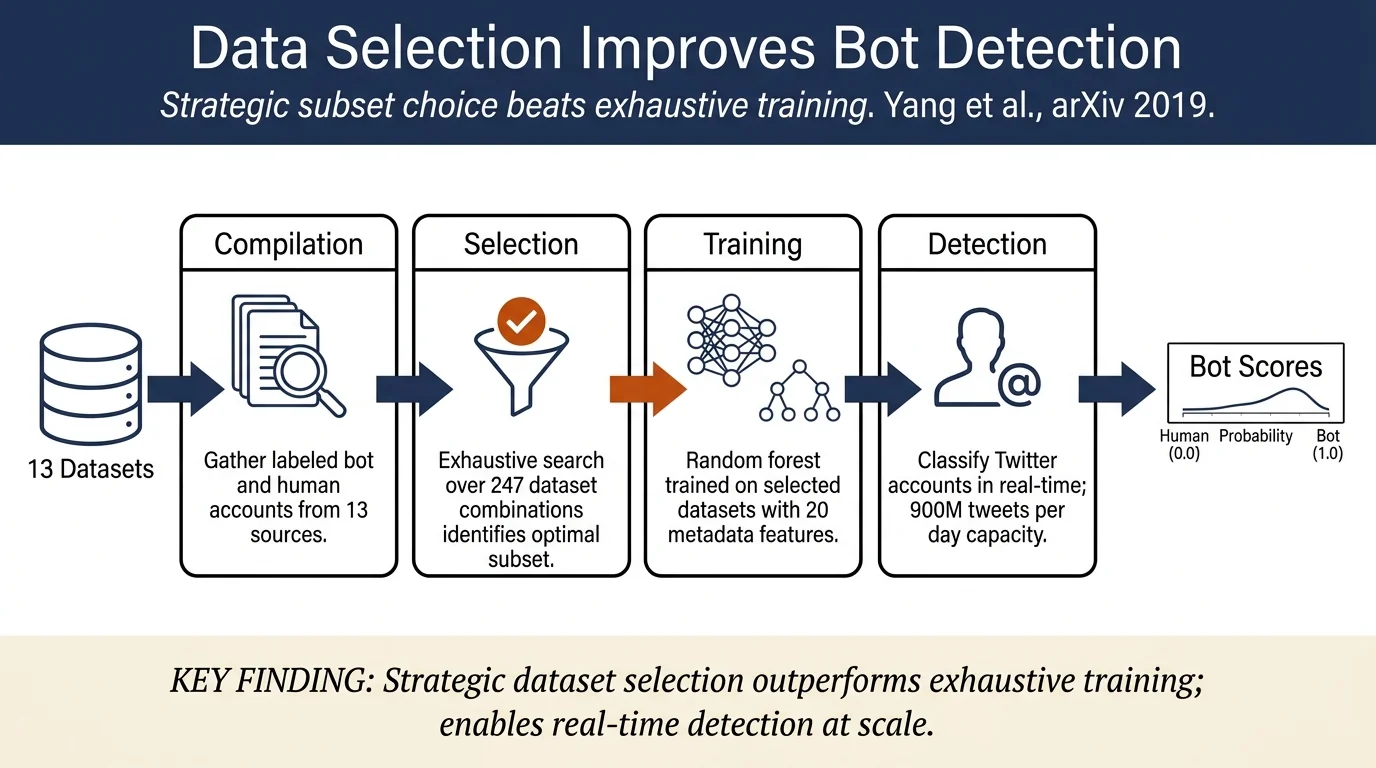
Scalable and Generalizable Social Bot Detection through Data SelectionThis paper addresses scalability and generalization challenges in social bot detection by proposing a framework using only 20 user metadata features, enabling real-time analysis of the full Twitter stream. The key insight is that strategic data selection—training on a carefully chosen subset of 13 compiled datasets—achieves better…
 Bots & coordinated campaignsDatasets & evaluation
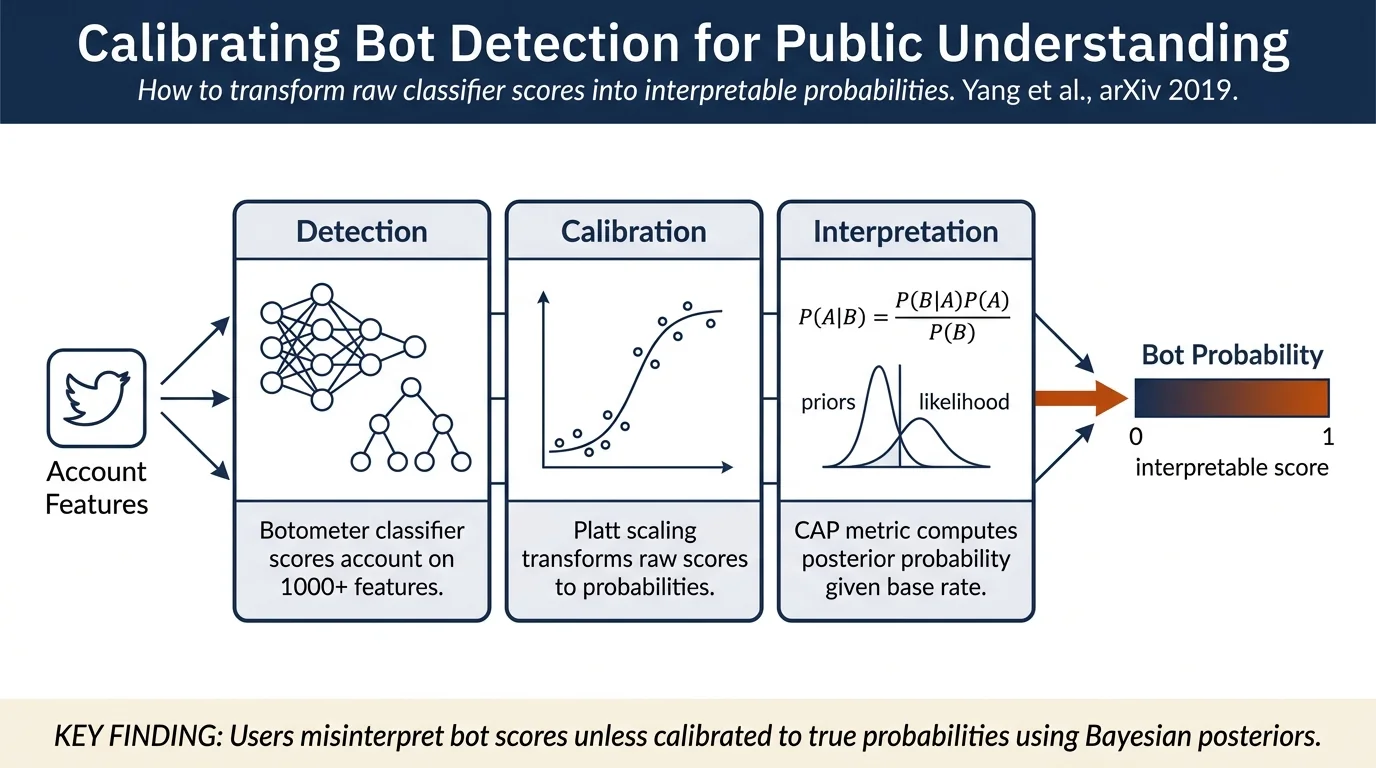
Arming the public with artificial intelligence to counter social botsThis paper reviews social bot types, their impact on online discourse, and detection methods, then presents Botometer as a case study in how detection tools are used and interpreted by the public. The authors conducted a user experience survey (731 participants) revealing that while users find the tool useful, they struggle with…
 Detection methodsDatasets & evaluation
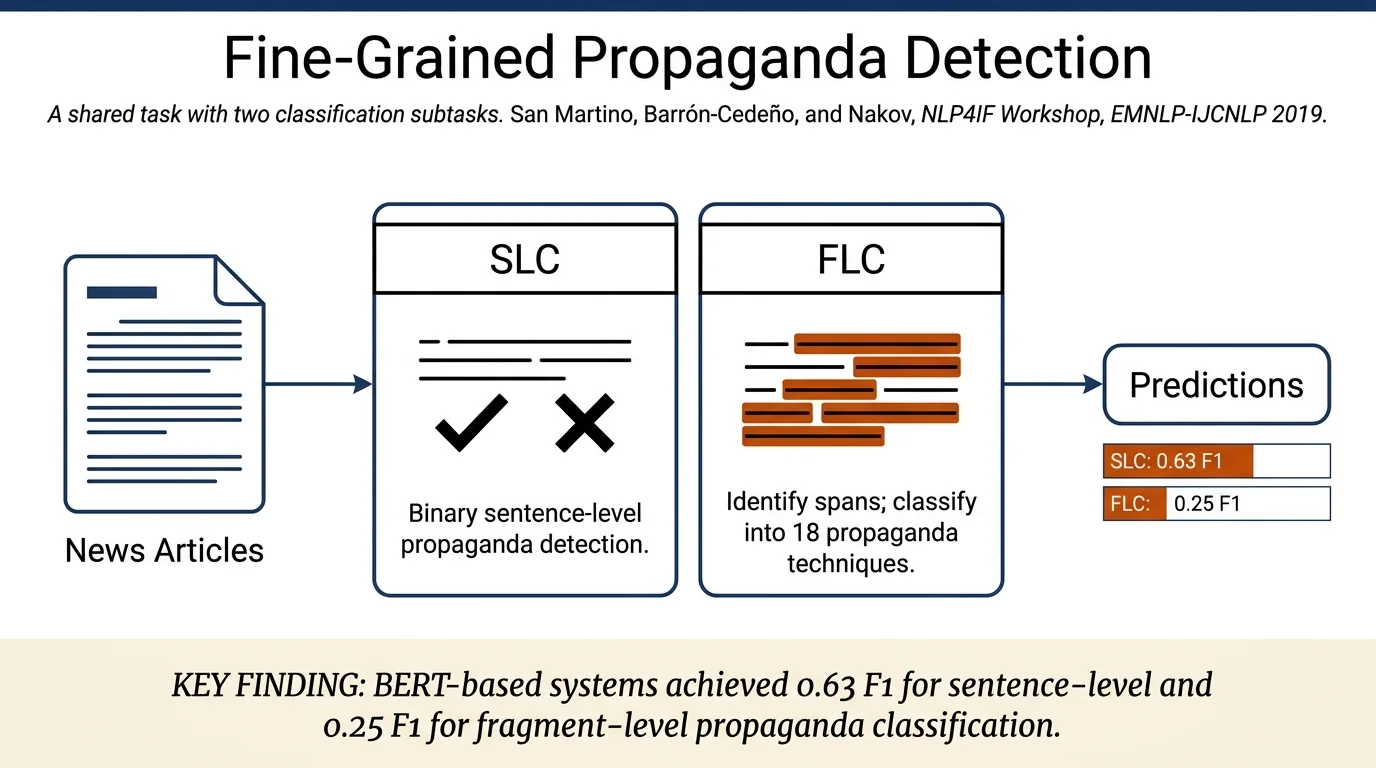
Findings of the NLP4IF-2019 Shared Task on Fine-Grained Propaganda DetectionThis paper reports findings from a shared task on fine-grained propaganda detection in news articles, featuring two subtasks: fragment-level identification and classification into 18 propaganda techniques, and sentence-level binary propaganda detection. The task attracted 90 registered teams with 39 making submissions; winning systems…
 Deepfakes & multimodalDetection methods
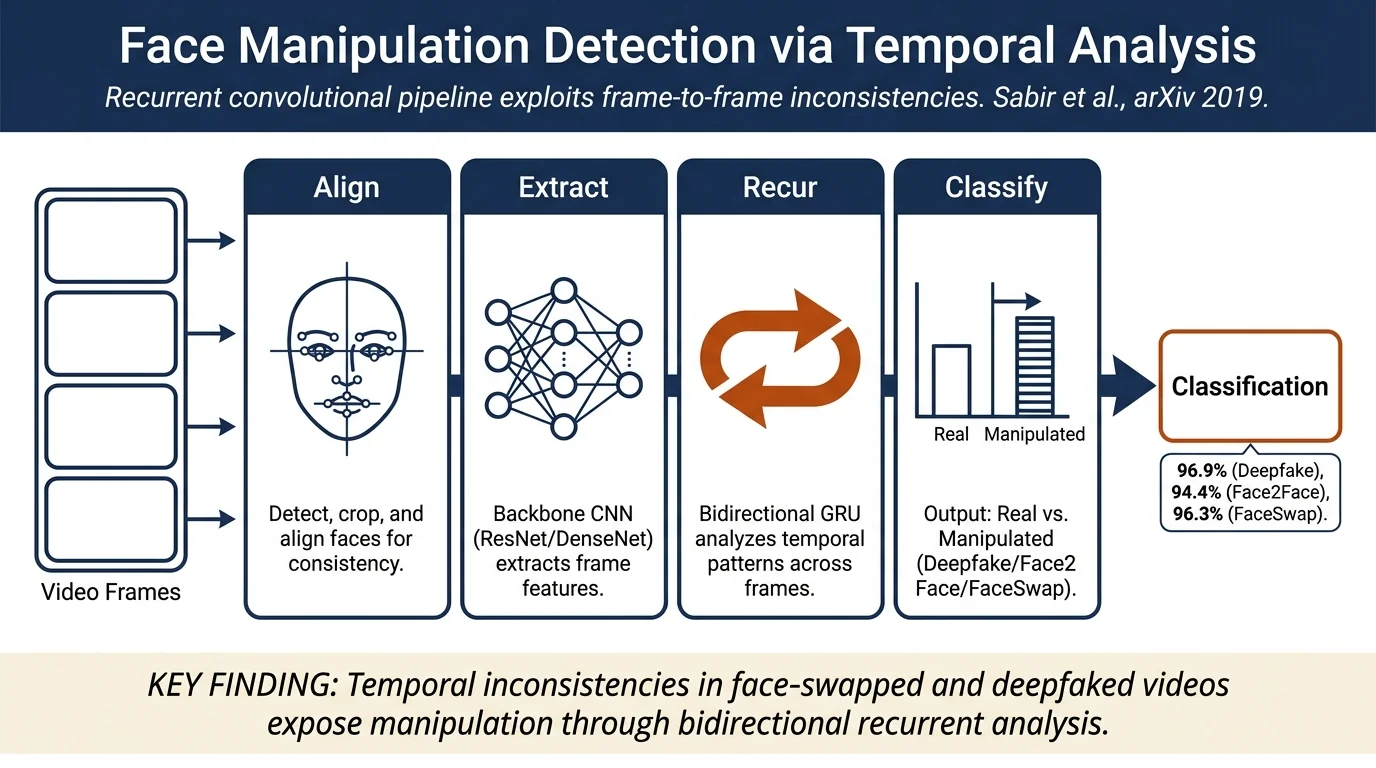
Recurrent Convolutional Strategies for Face Manipulation Detection in VideosThis paper proposes using recurrent convolutional networks to detect face manipulations (Deepfake, Face2Face, FaceSwap) in videos by exploiting temporal discrepancies across frames. Face preprocessing with alignment and bidirectional recurrent networks achieve state-of-the-art on FaceForensics++ with up to 4.55% improvement over prior…
 Deepfakes & multimodalDetection methods
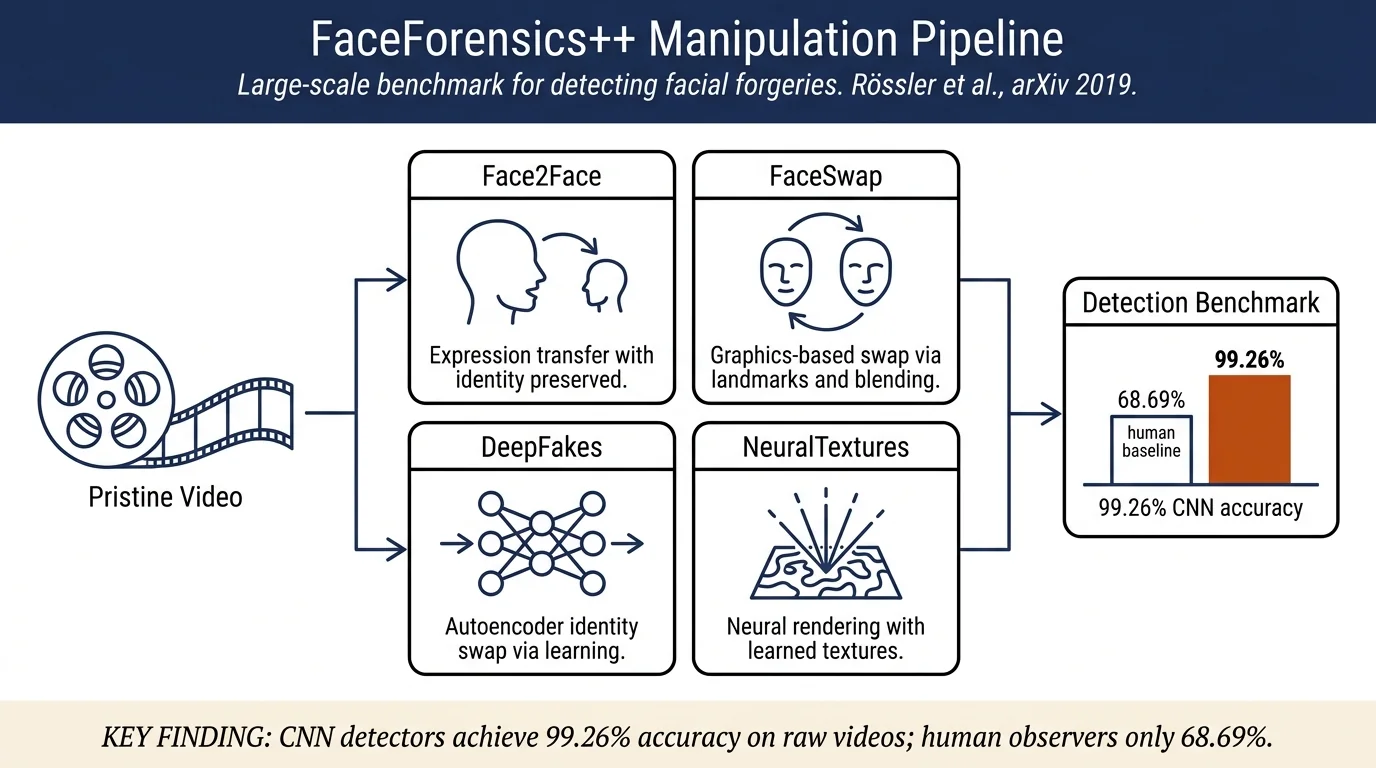
FaceForensics++: Learning to Detect Manipulated Facial ImagesFaceForensics++ introduces a large-scale benchmark (1.8+ million manipulated images from 1,000+ videos) for detecting facial manipulations created with four state-of-the-art methods: Face2Face, FaceSwap, DeepFakes, and NeuralTextures. The paper comprehensively evaluates detection methods from stegananalysis to deep learning,…
 Datasets & evaluationSpread & networks
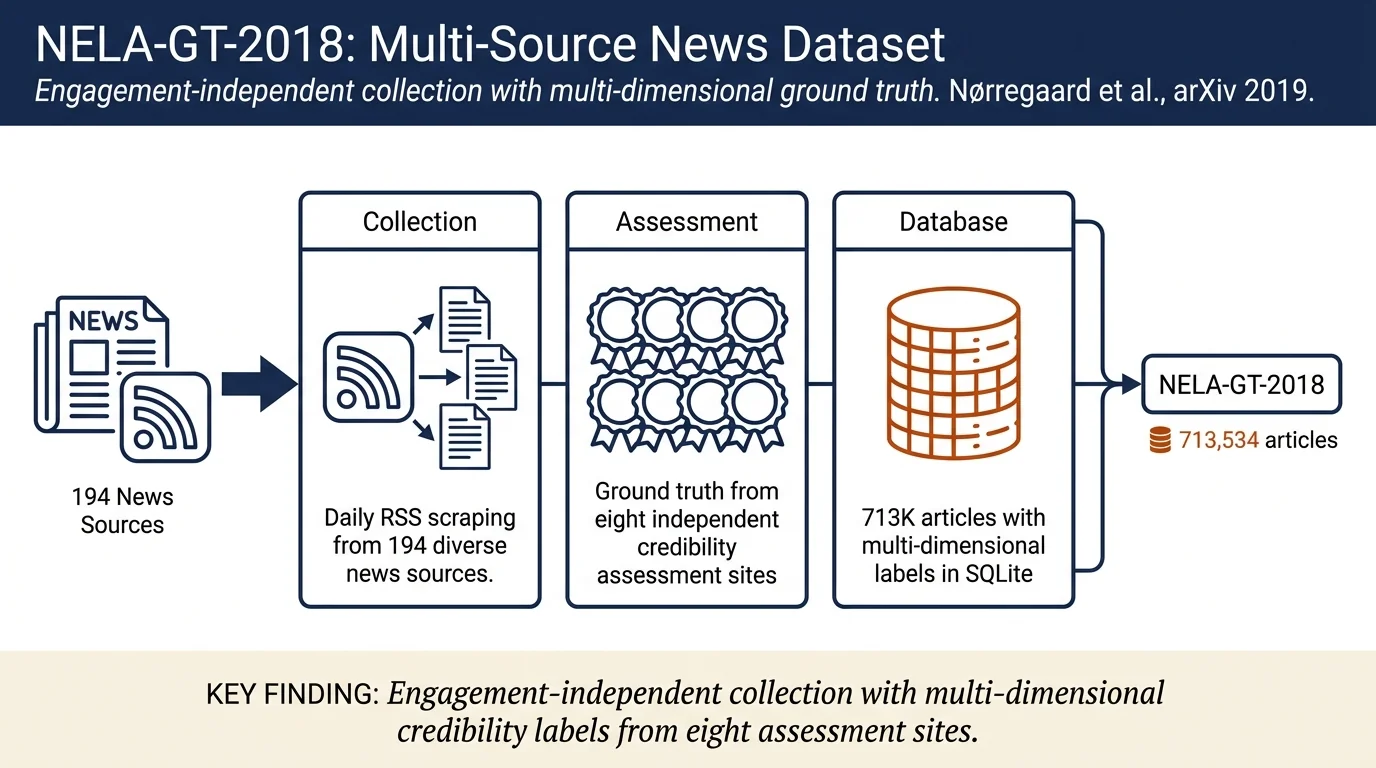
NELA-GT-2018: A Large Multi-Labelled News Dataset for The Study of Misinformation in News ArticlesNELA-GT-2018 is a large, engagement-independent collection of 713,534 news articles from 194 sources across 10 months (Feb–Nov 2018). It combines multi-source-level ground truth labels from eight independent assessment sites (NewsGuard, Pew Research, Wikipedia, OpenSources, Media Bias/Fact Check, AllSides, BuzzFeed News, PolitiFact)…
 Datasets & evaluationDeepfakes & multimodal
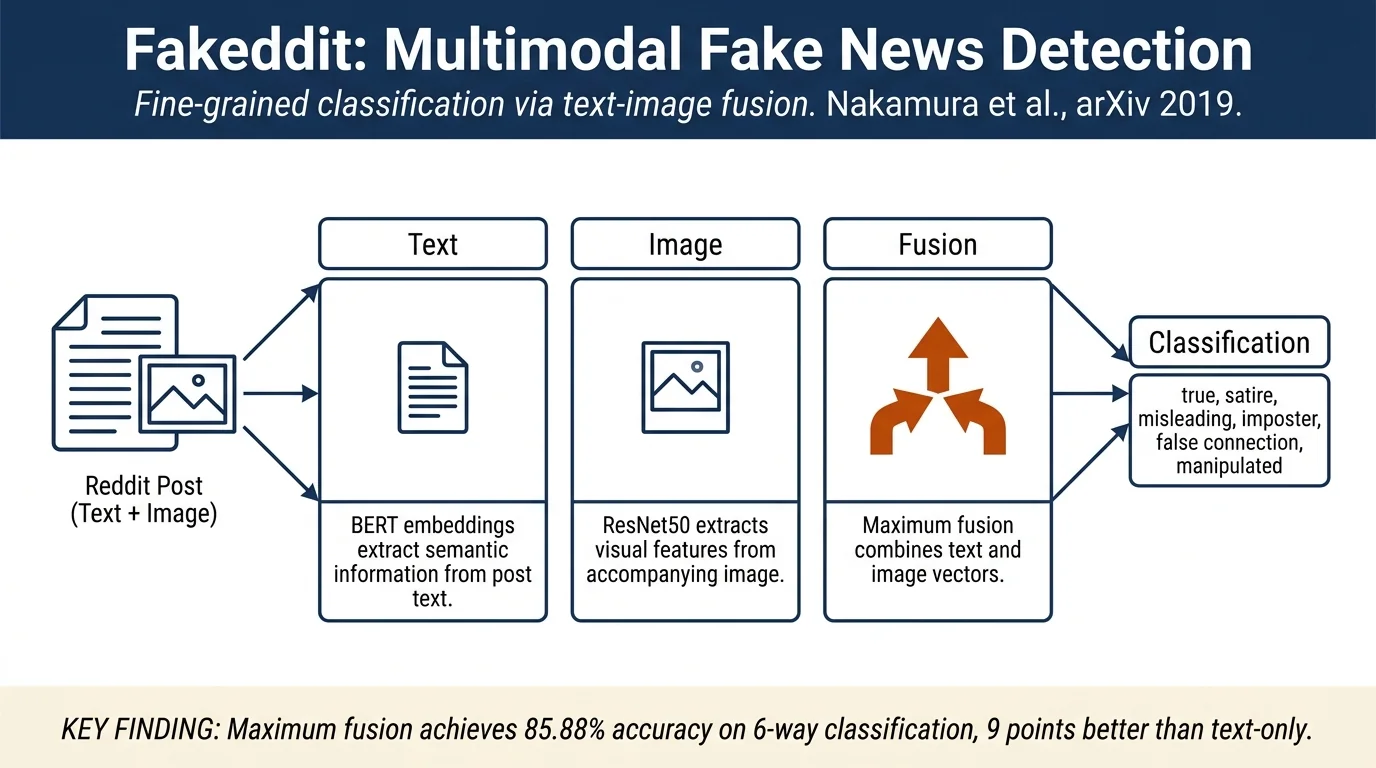
r/Fakeddit: A New Multimodal Benchmark Dataset for Fine-grained Fake News DetectionFakeddit is a large-scale multimodal fake news detection dataset with over 1 million Reddit samples labeled with 2-way, 3-way, and 6-way classification schemes. Multimodal models combining text (BERT) and image (ResNet50) features achieve 86.0% accuracy on 6-way classification, demonstrating the importance of jointly leveraging text and…
 Detection methodsSpread & networks
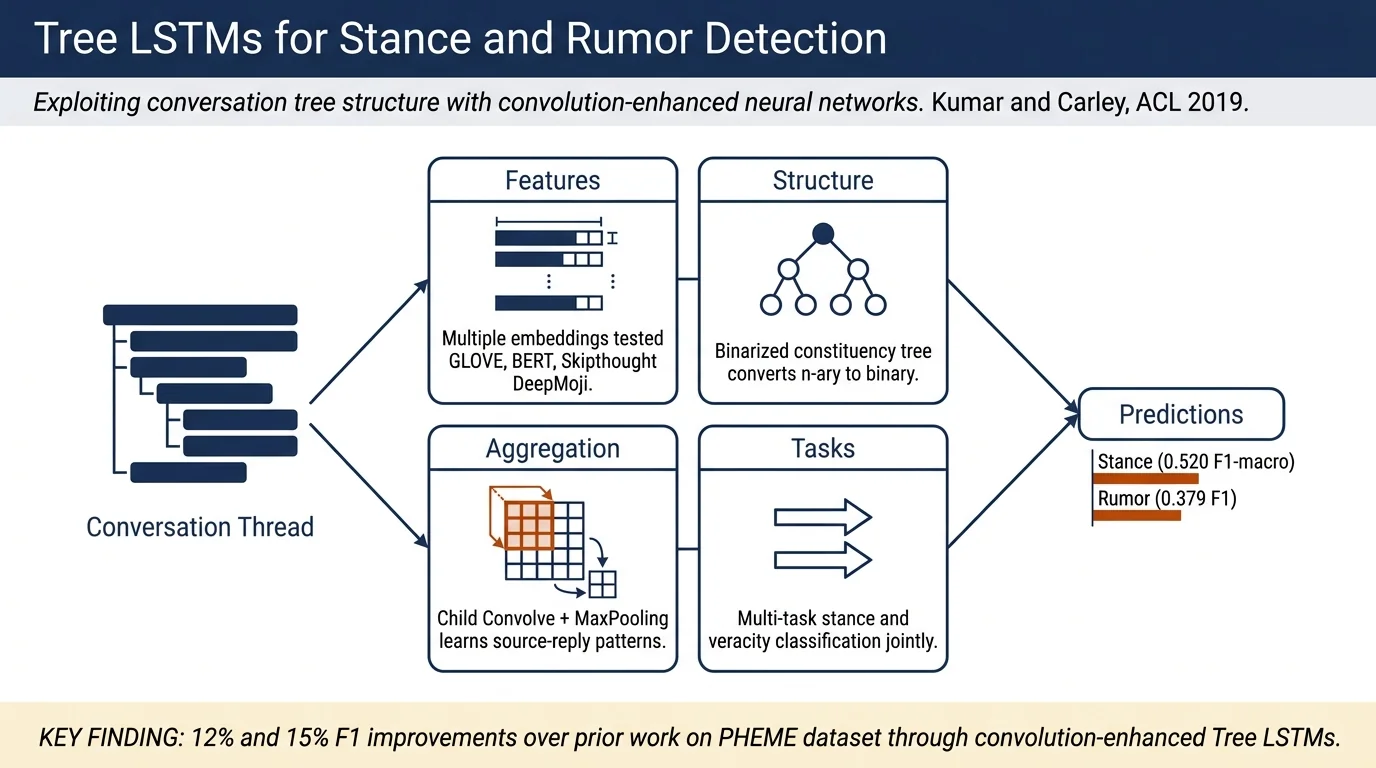
Tree LSTMs with Convolution Units to Predict Stance and Rumor Veracity in Social Media ConversationsProposes Tree LSTM and Binarized Constituency Tree (BCTree) LSTM architectures enhanced with convolution units to classify stance and predict rumor veracity in social media conversation threads. The approach exploits the tree structure inherent in threaded conversations (source post with nested replies) and combines it with convolutional…
 Detection methodsDatasets & evaluation
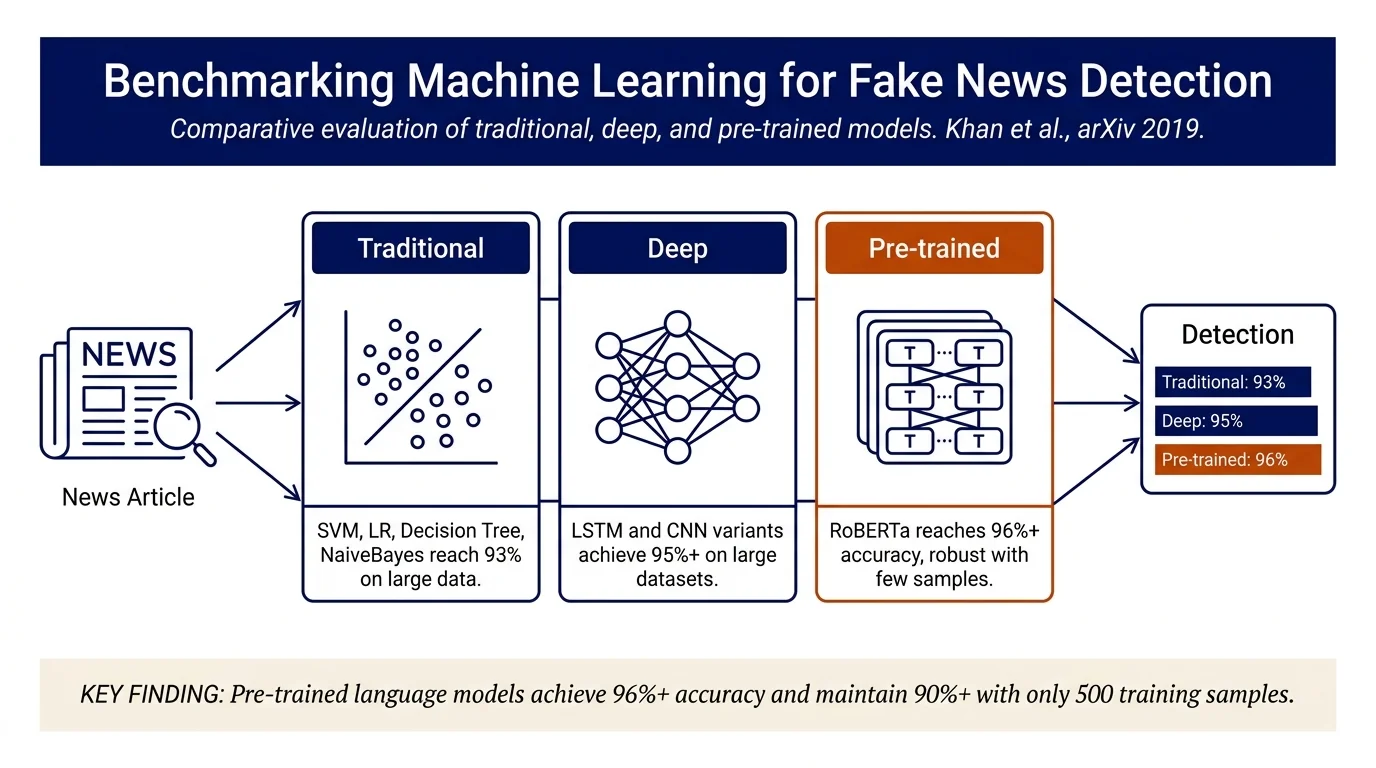
A Benchmark Study of Machine Learning Models for Online Fake News DetectionComprehensive benchmark of 19 machine learning approaches across three fake news datasets (LIAR, Fake or Real News, and an 80k-news combined corpus spanning politics, health, sports, and other topics). Key finding: BERT-based pre-trained models (especially RoBERTa) substantially outperform traditional and deep learning approaches,…
 LLMs & generative AIDetection methods
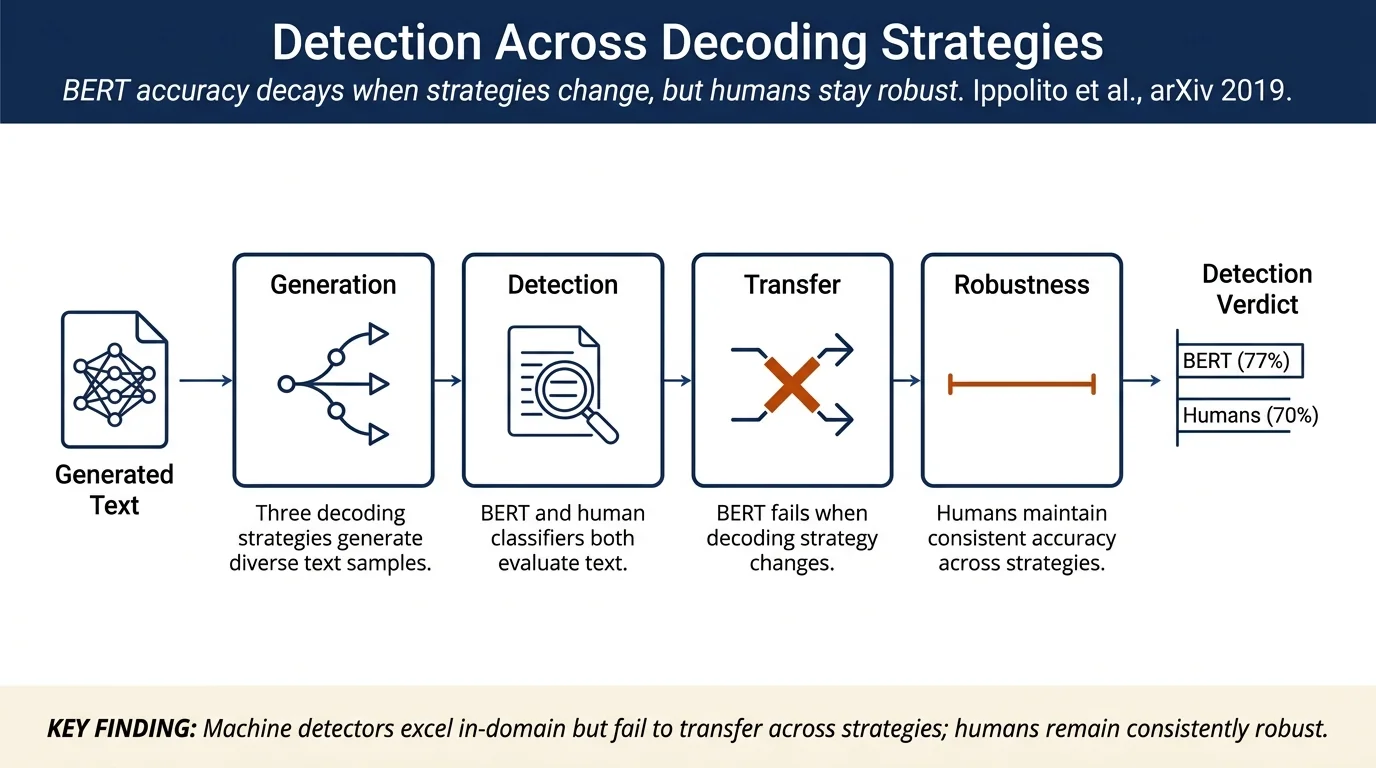
Automatic Detection of Generated Text is Easiest when Humans are FooledIppolito et al. investigate the complementary abilities of humans and machines to detect machine-generated text from GPT-2 under various decoding strategies. They find that fine-tuned BERT detectors outperform humans (achieving 80%+ accuracy on long excerpts versus 71% for expert human raters), but detector performance is highly…
 Spread & networksDatasets & evaluation
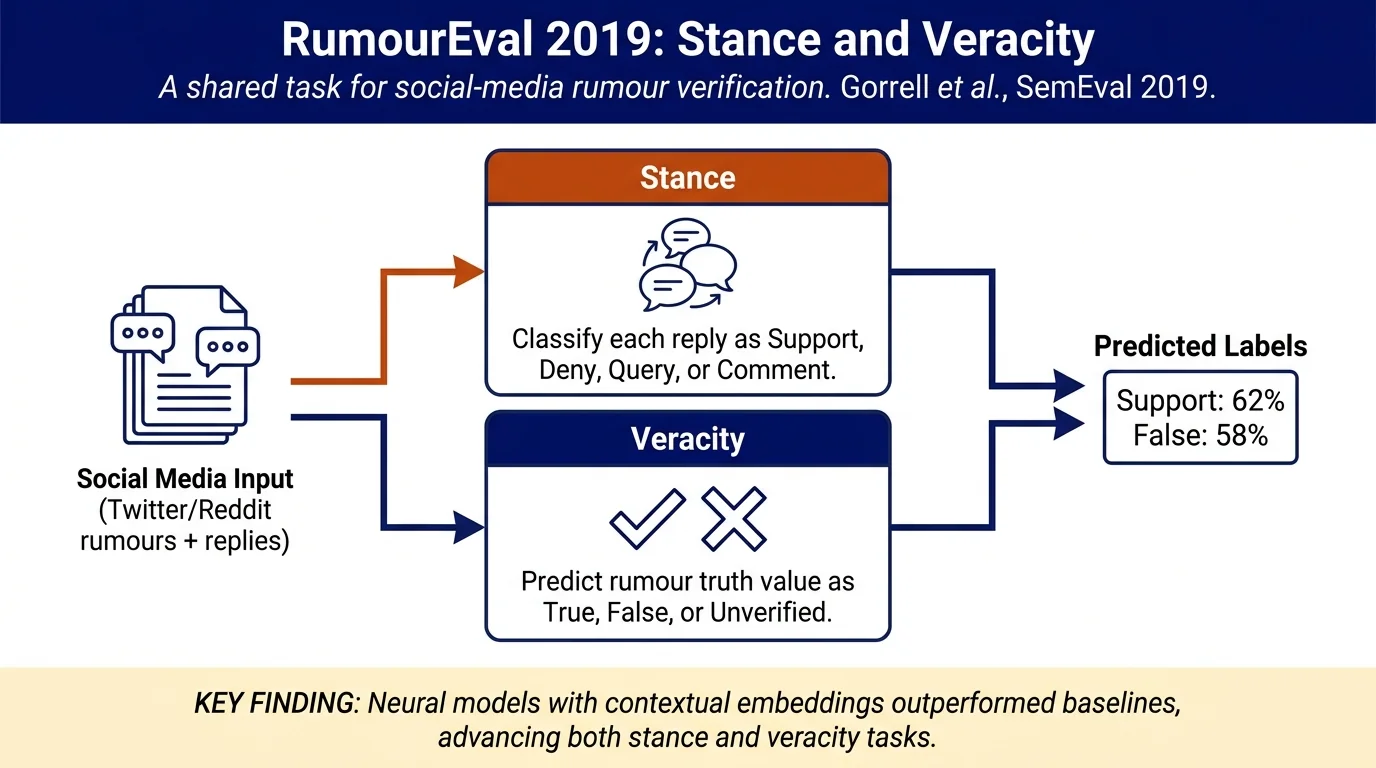
RumourEval 2019: Determining Rumour Veracity and Support for RumoursRumourEval 2019 is a shared task for rumour stance detection and veracity prediction on social media. Extending the 2017 edition, it introduces Reddit data alongside Twitter, provides datasets annotated for SDQC stance (Support/Deny/Query/Comment) and three-way veracity labels, and received 22 system submissions showing that modern…
 LLMs & generative AIDetection methods
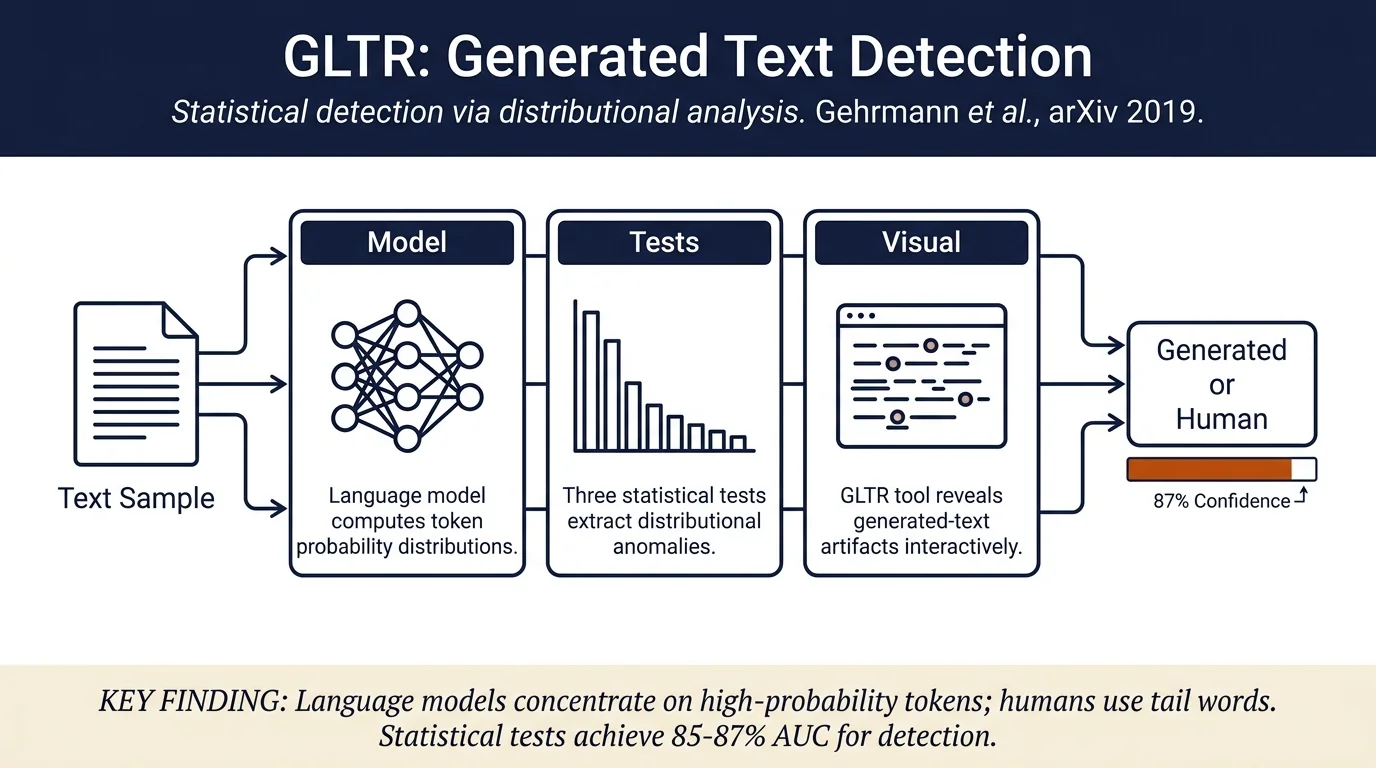
GLTR: Statistical Detection and Visualization of Generated TextGehrmann et al. present GLTR, a visual tool for detecting AI-generated text by analyzing statistical anomalies in language model output. The key insight is that language models sample from the head of the distribution (high-probability words), whereas humans use a wider vocabulary including low-probability choices.