Explore papers
Filter by research area, year and venue. Every filter is in the address bar, so you can share a view as a link.
 Deepfakes & multimodalDetection methods
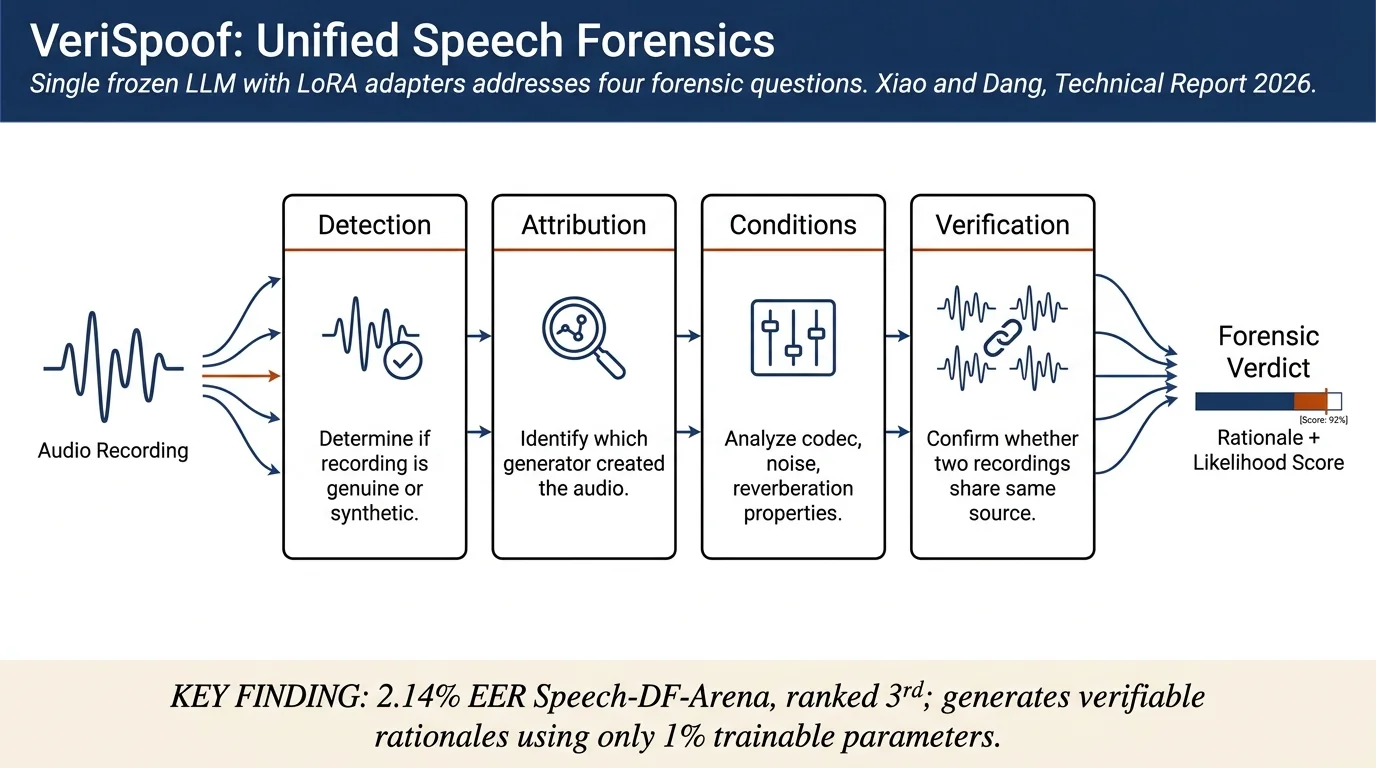
VeriSpoof: Beyond Real or Fake with One Audio LLMVeriSpoof is an audio language model system that unifies multiple forensic tasks in a single neural framework: detecting whether a speech recording is synthetic, identifying which generator produced it, analyzing recording conditions, and verifying whether two recordings share a source. The system achieves state-of-the-art results on…
 Deepfakes & multimodalDatasets & evaluation
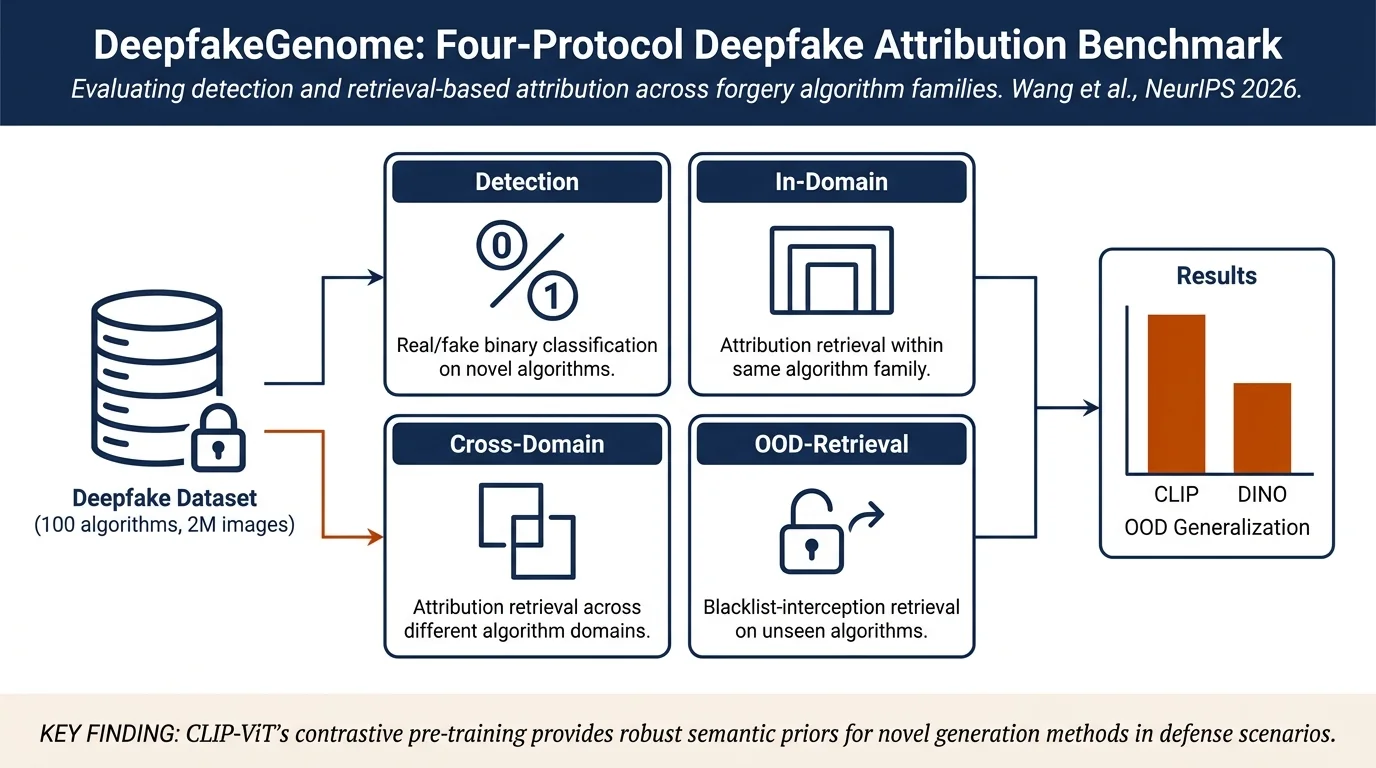
DeepfakeGenome: Toward Next-Generation Deepfake AttributionDeepfakeGenome (DFG) is a large-scale benchmark for deepfake detection and attribution covering 100 facial forgery algorithms and 2M images — 4–100× larger than prior benchmarks. The paper proposes 4 evaluation protocols using novel retrieval-based attribution metrics (mAP, Recall) instead of reject-class classification, and conducts…
 Deepfakes & multimodalDetection methods
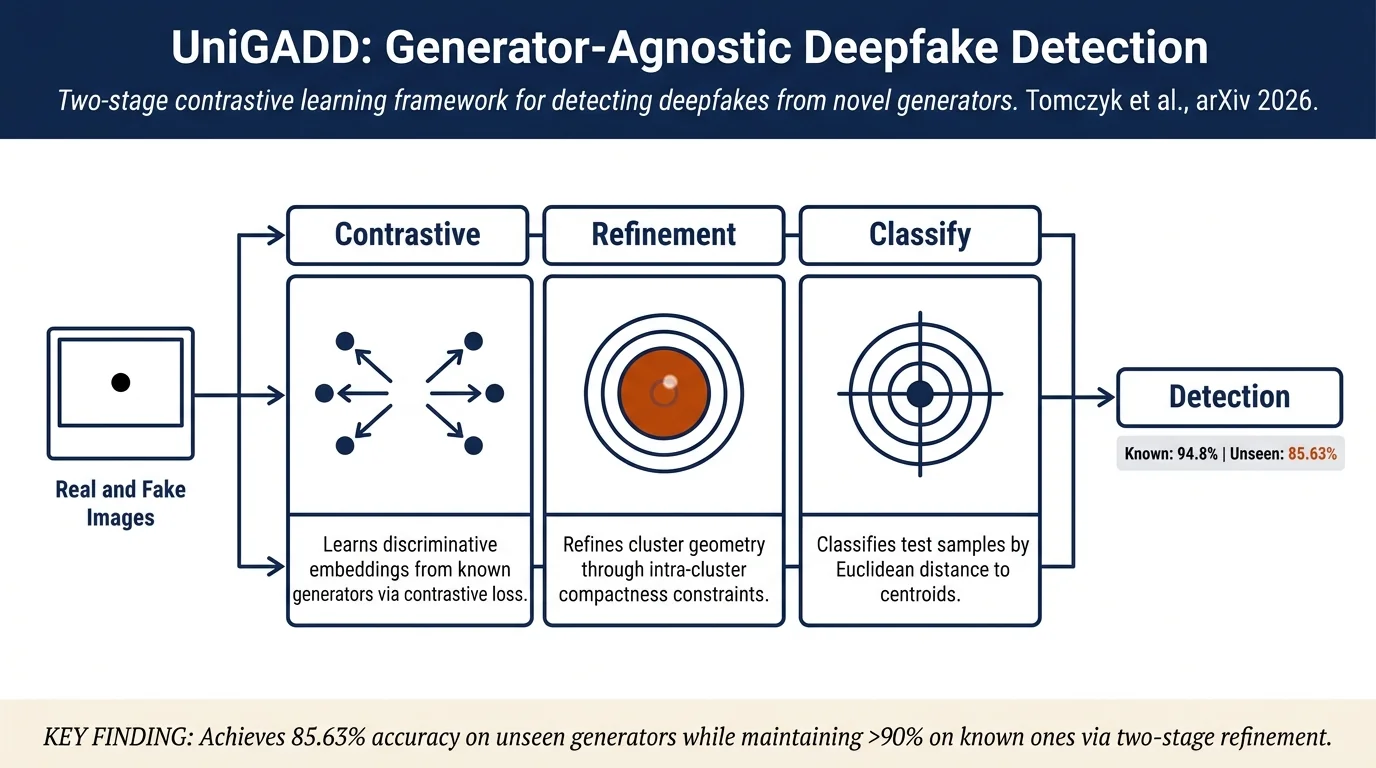
UniGADD: Universal Generator-Agnostic Deepfake DetectorUniGADD proposes a two-stage supervised contrastive learning framework for detecting deepfakes from previously unseen generators. The method learns discriminative embeddings from known fake generators in stage one, then refines cluster structure via intra-cluster compactness constraints in stage two.
 Deepfakes & multimodalDetection methods
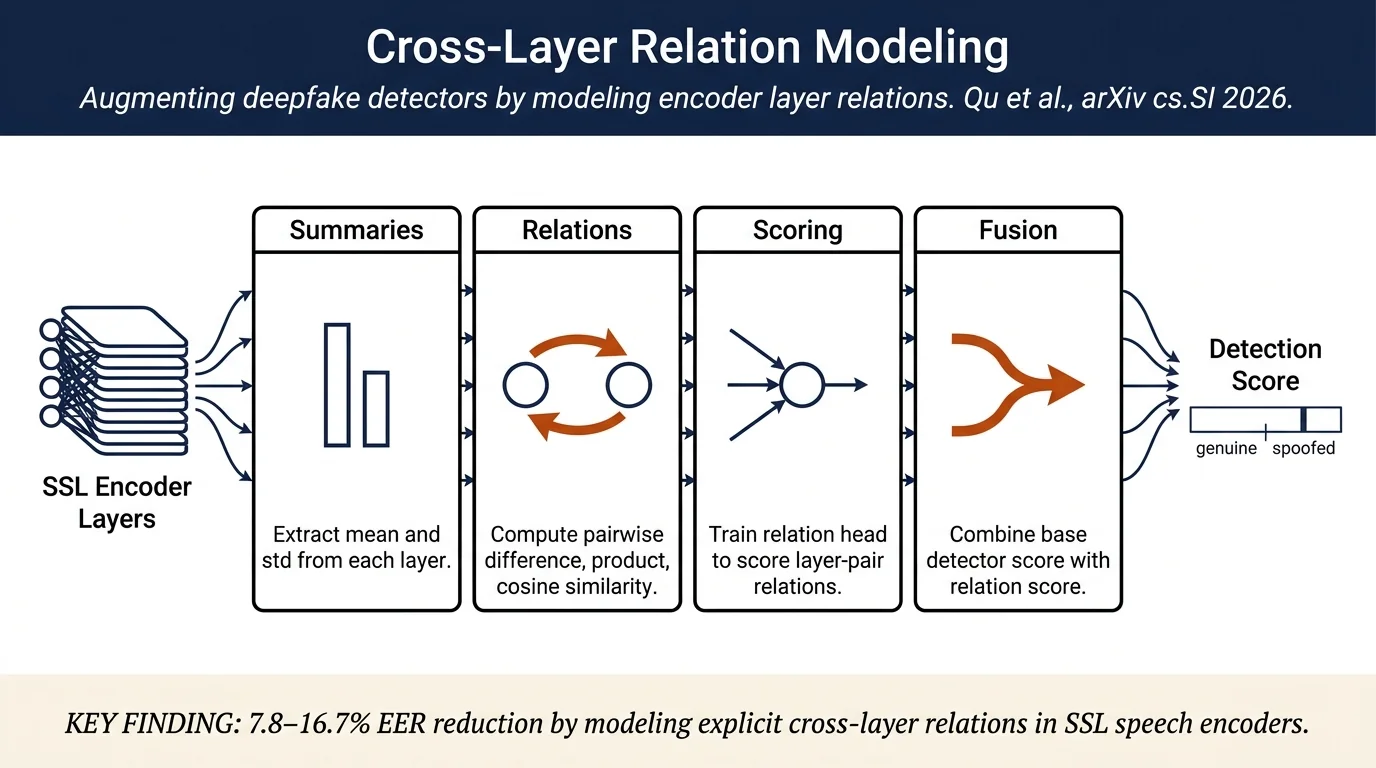
CLRM: Cross-Layer Relation Modeling for Audio Deepfake DetectionAudio deepfake detection (ADD) distinguishes authentic speech from synthetic or manipulated speech. Existing methods either select informative layers from self-supervised learning (SSL) speech encoders or aggregate features across layers, but this discards useful variation in how different layers represent genuine vs. spoofed speech.
 Deepfakes & multimodalDetection methods
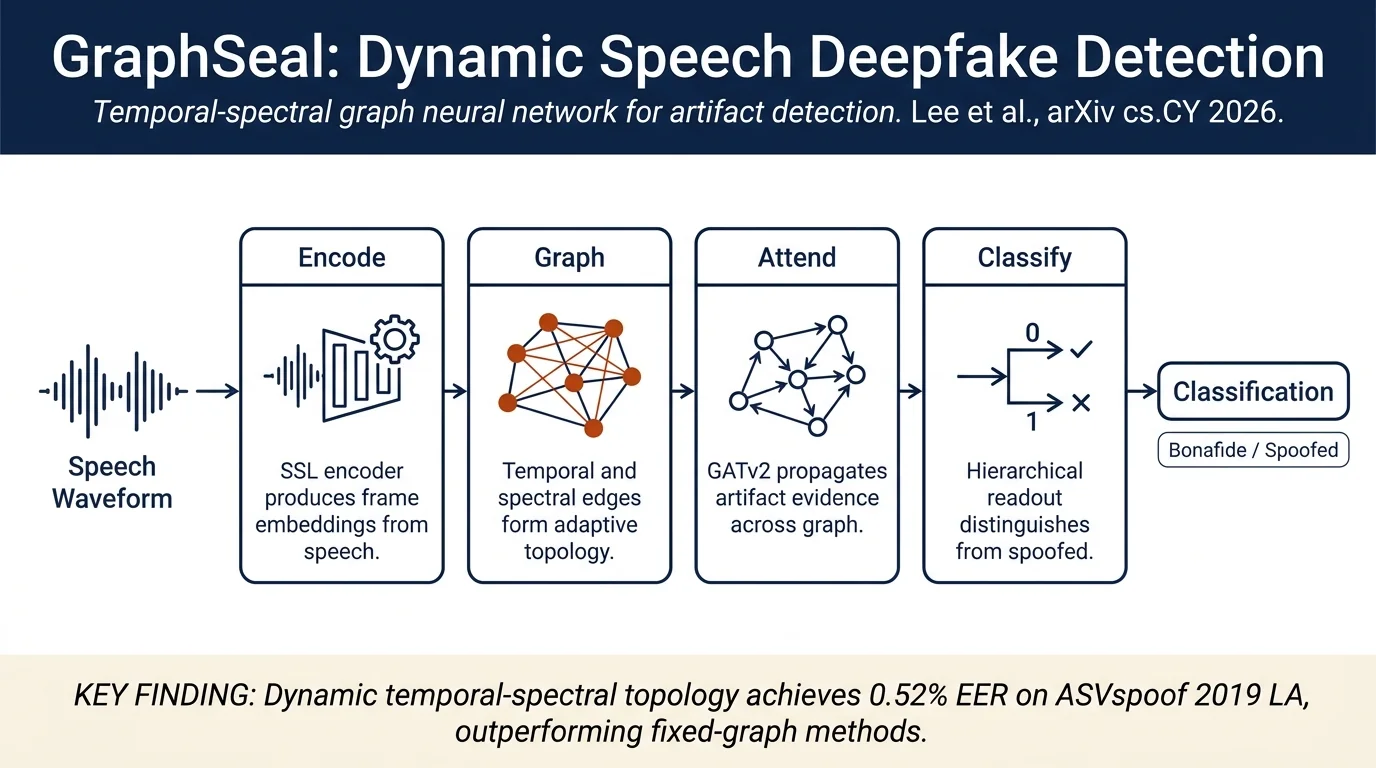
GraphSeal: Graph-Augmented Speech Deepfake Detection via Temporal-Spectral Artifact PropagationGraphSeal proposes a dynamic temporal-spectral graph neural network for speech deepfake detection that outperforms fixed-topology baselines on generalization tasks. Unlike prior graph-based anti-spoofing methods that use feature-extraction-determined topologies, GraphSeal constructs utterance-specific edges from both temporal adjacency…
 Deepfakes & multimodalDetection methods
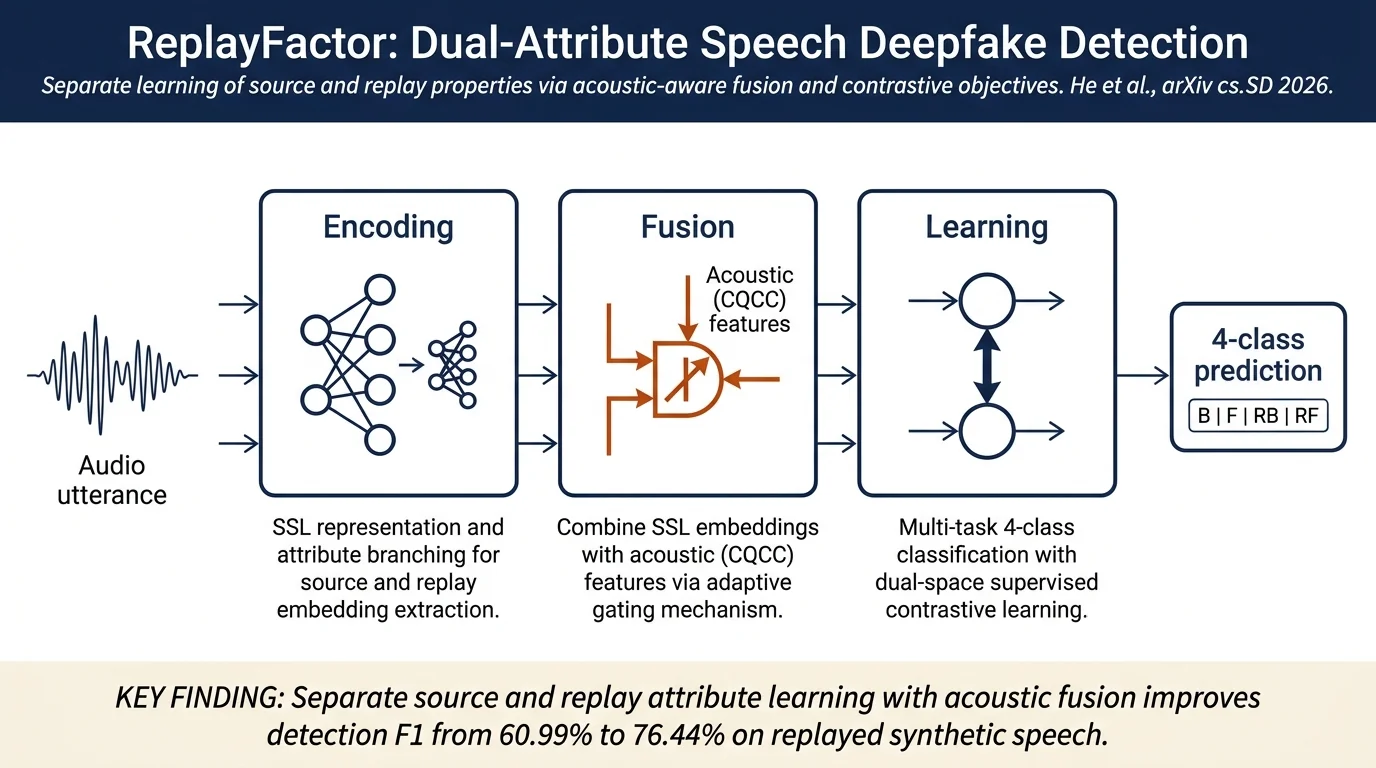
ReplayFactor: Replay-Aware Dual-Attribute Learning for Practical Speech Deepfake DetectionExisting speech deepfake detectors fail on physically replayed synthetic speech (played through a loudspeaker and re-recorded), a low-cost, practical threat to voice authentication systems. ReplayFactor addresses this by learning both source authenticity (human vs. generated) and replay presence (non-replayed vs. replayed) via SSL-based…
 Deepfakes & multimodalLLMs & generative AI
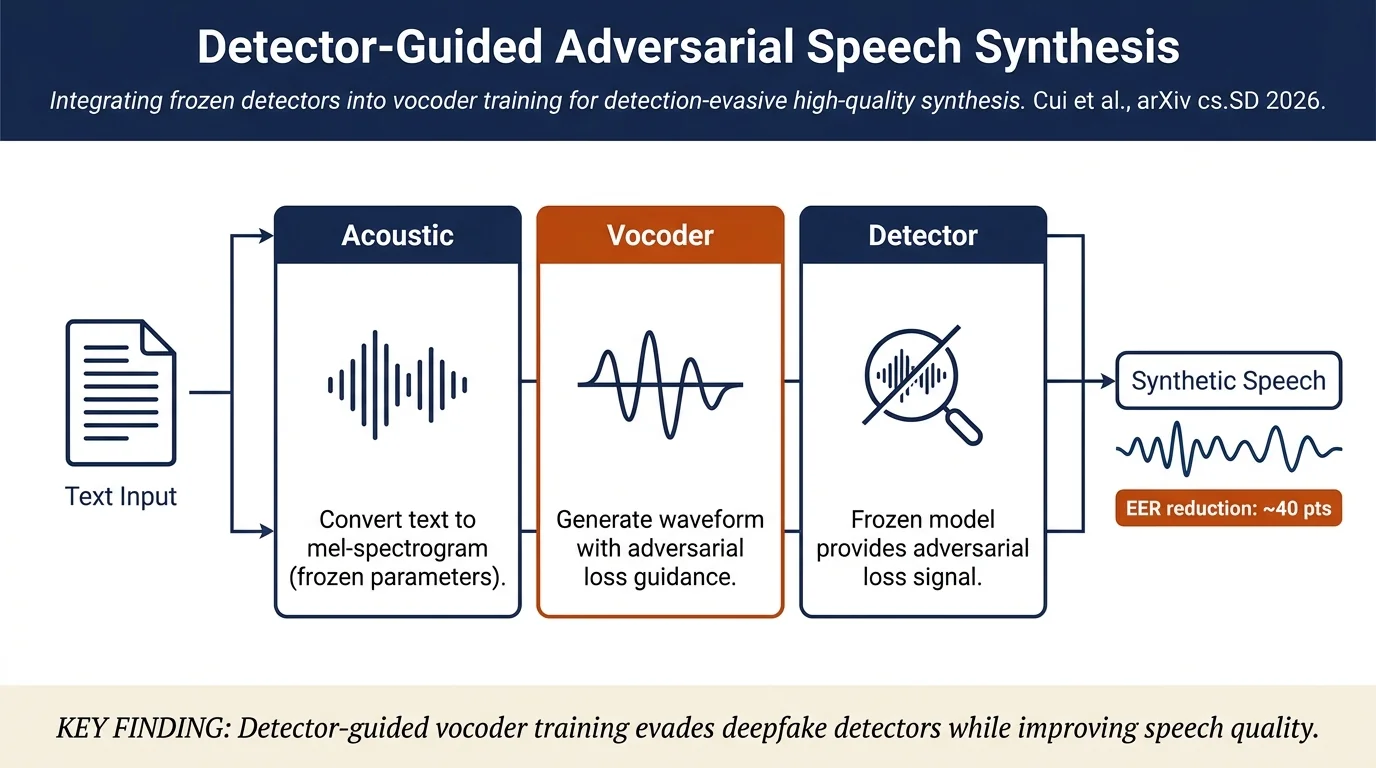
Detector-Guided Vocoder Training for Adversarial Text-to-Speech SynthesisThis paper presents a method to generate synthetic speech that evades deepfake detectors by integrating detector loss directly into vocoder training, rather than applying post-hoc perturbations. The approach fine-tunes a BigVGAN vocoder while freezing the acoustic model and detector, generating adversarial speech that retains high…
 Platforms, policy & societyDeepfakes & multimodal
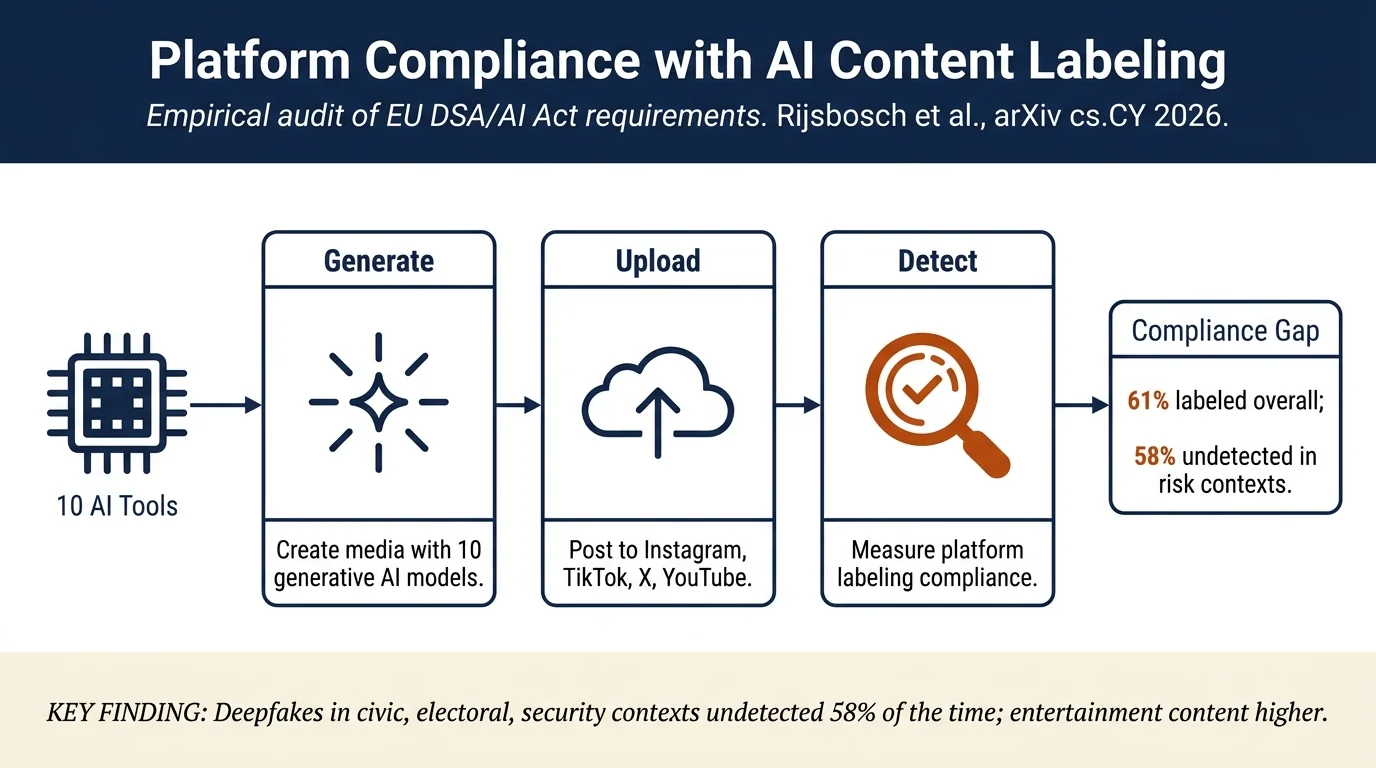
Drowning in AI Slop: How Social Media Platforms (Do Not) Label AI and Deepfake Content under EU lawThis paper conducts a legally grounded empirical audit of AI-labeling practices across Instagram, TikTok, X, and YouTube, testing how well platforms comply with EU legal obligations to label AI-generated and deepfake content. Using uploads of content generated by 10 generative AI tools, the authors find that platforms labeled only 36 of…
 Fact-checking & verificationLLMs & generative AI
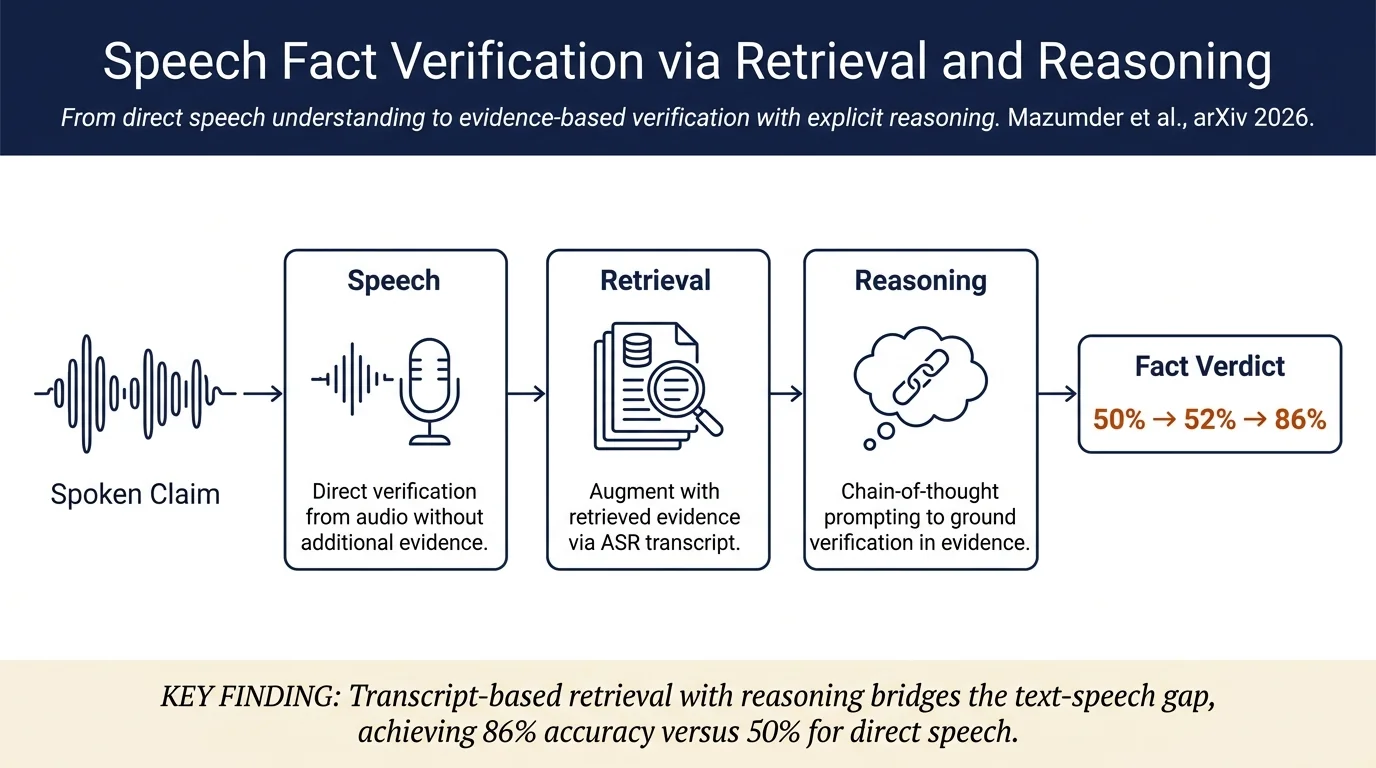
To Trust or Not to Trust: Retrieval-Augmented Fact Checking in SpeechLarge Audio Language Models (LALMs) exhibit a significant text-speech modality gap: they verify written claims reliably but fail on spoken ones, even from the same model. The paper introduces VeriSpeak, a benchmark of 3,879 spoken claims with temporal, geographical, and relational facts, and demonstrates that retrieval-augmented LALMs…
 Deepfakes & multimodalDatasets & evaluation
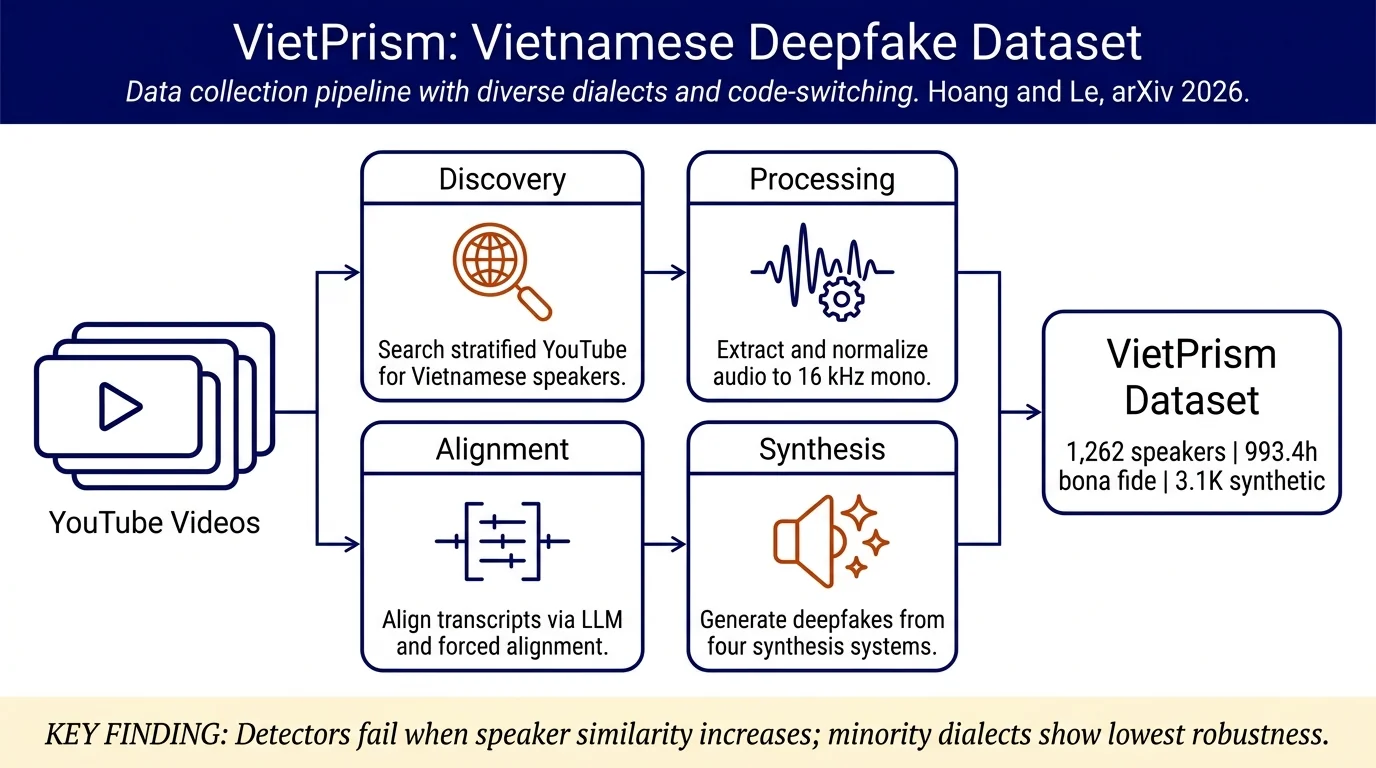
VietPrism: A Large-Scale Vietnamese Speech and Deepfake Corpus with Diverse Dialects and Code-SwitchingVIETPRISM is a large-scale Vietnamese speech dataset combining 993.4 hours of bona fide utterances from 1,262 speakers with 3.1K hours of synthetically generated speech from four deepfake systems. The dataset uniquely provides transcripts, dialect annotations, speaker identities, and natural Vietnamese–English code-switching coverage.
 Deepfakes & multimodalDatasets & evaluation
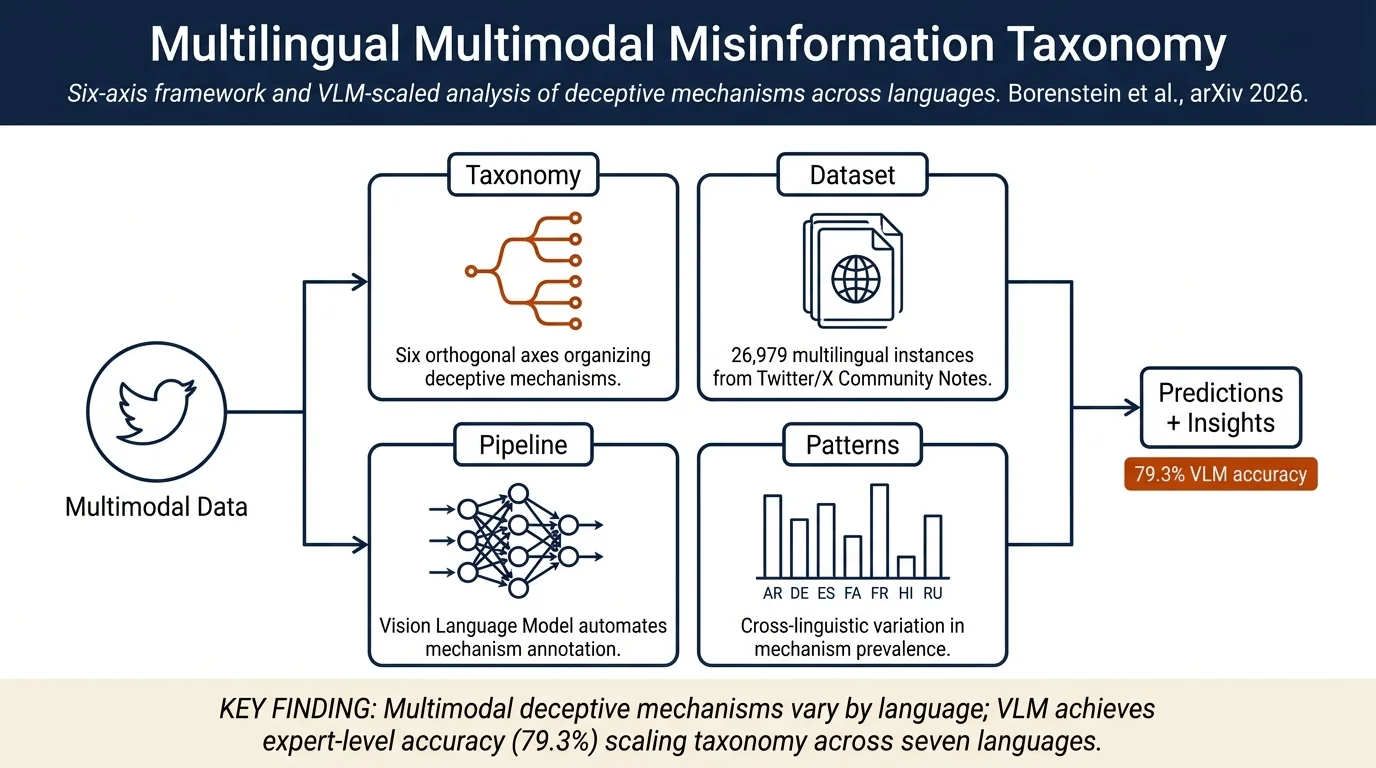
MMMMM: A Unified Taxonomy for Investigating the Mechanisms of Multilingual MultiModal MisinformationMultimodal misinformation (images paired with misleading text) is poorly understood compared to text-only fake news, hampered by fragmented taxonomies and the complexity of annotating cross-modal relationships at scale. This work proposes a unified taxonomy of multimodal misinformation mechanisms across six orthogonal axes…
 Deepfakes & multimodalDetection methods
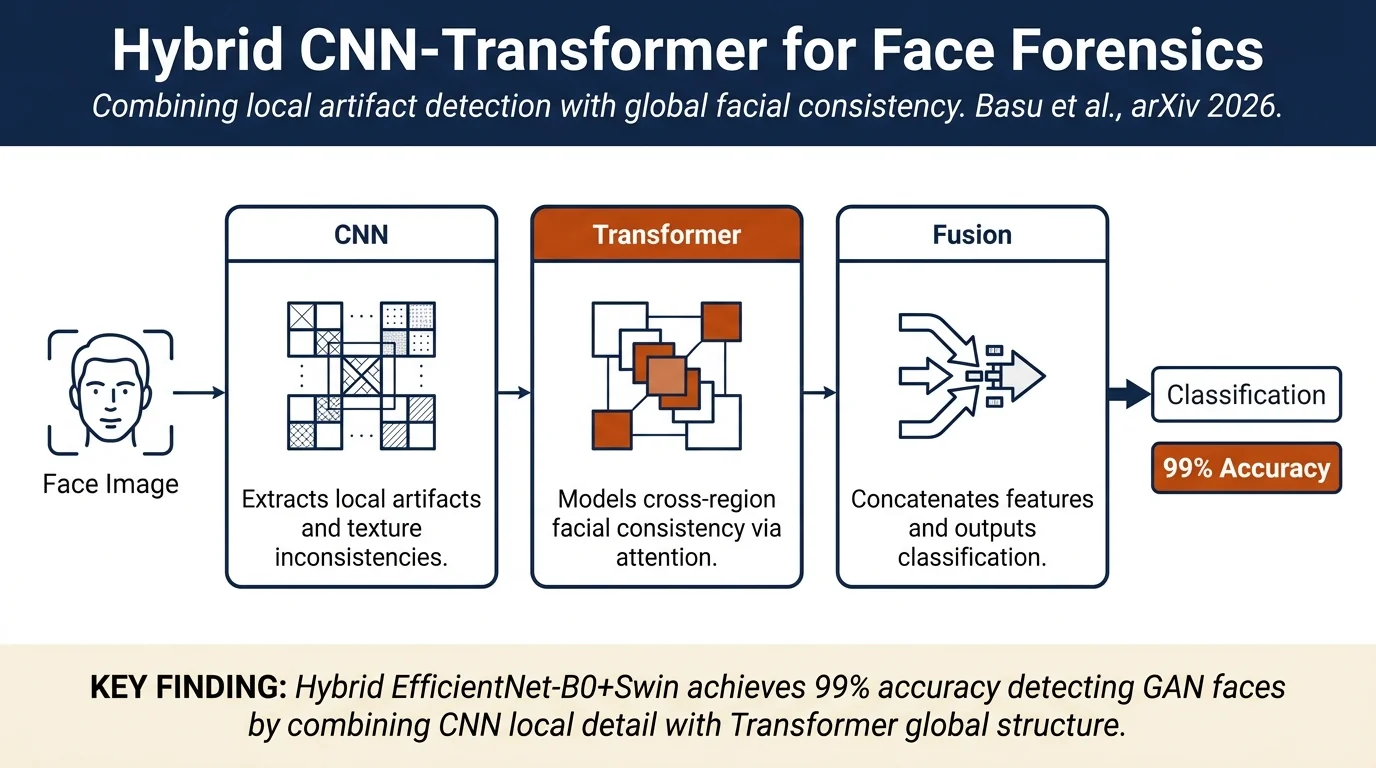
Swin Meets EfficientNet: Lightweight Architectures for GAN-Based Face ForensicsProposes lightweight Swin-Transformer and hybrid EfficientNet-Swin architectures for detecting GAN-generated synthetic faces under computational constraints. The hybrid EfficientNet-B0+Swin model achieves 99% accuracy and 99.44% recall on the 140K Real and Fake Faces dataset, combining convolutional local feature extraction with…
 Datasets & evaluationDeepfakes & multimodal
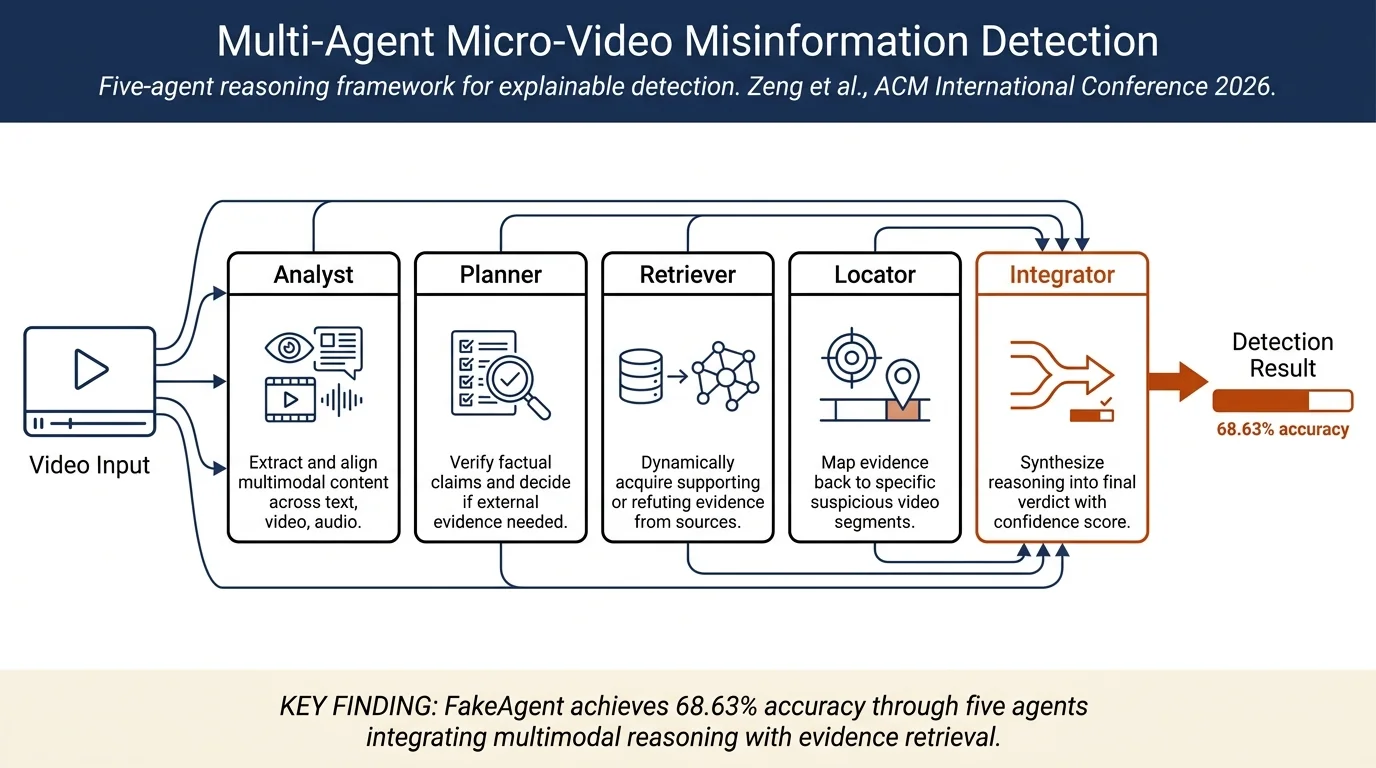
From Manipulation to Mistrust: Explaining Diverse Micro-Video Misinformation for Robust Debunking in the WildThe paper introduces WildFakeBench, a benchmark of 10,000+ real-world micro-videos spanning diverse misinformation types (manipulation, bias, AI-generated content, out-of-context) from six social platforms. The authors propose FakeAgent, a multi-agent reasoning framework combining neural networks and large language models, which achieves…
 Deepfakes & multimodalDetection methods
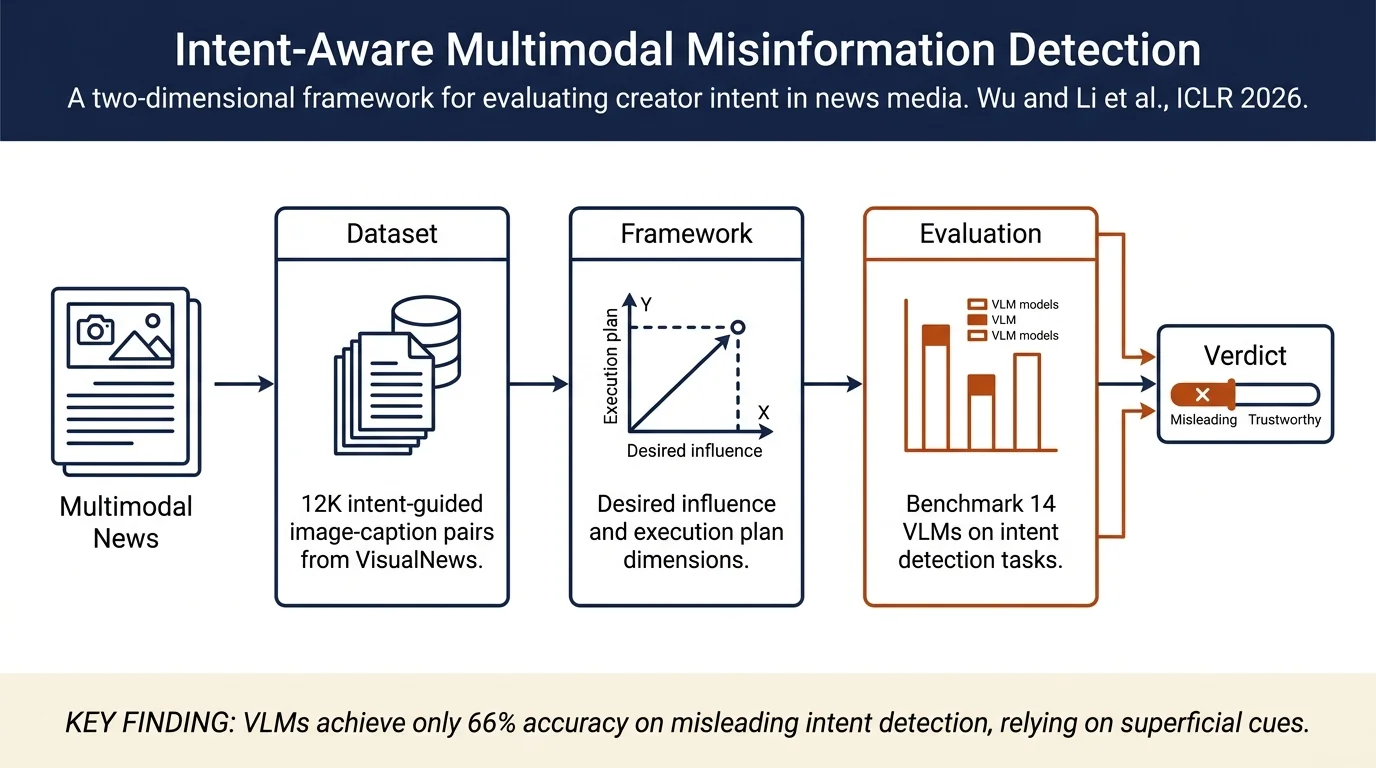
Seeing Through Deception: Uncovering Misleading Creator Intent in Multimodal News with Vision-Language ModelsThis paper introduces DECEPTIONDECODED, a benchmark of 12,000 image-caption pairs for evaluating multimodal misinformation detection with focus on creator intent. The authors find that state-of-the-art vision-language models struggle with intent reasoning and rely on superficial cues, motivating a framework for intent-aware multimodal…
 LLMs & generative AIDetection methods
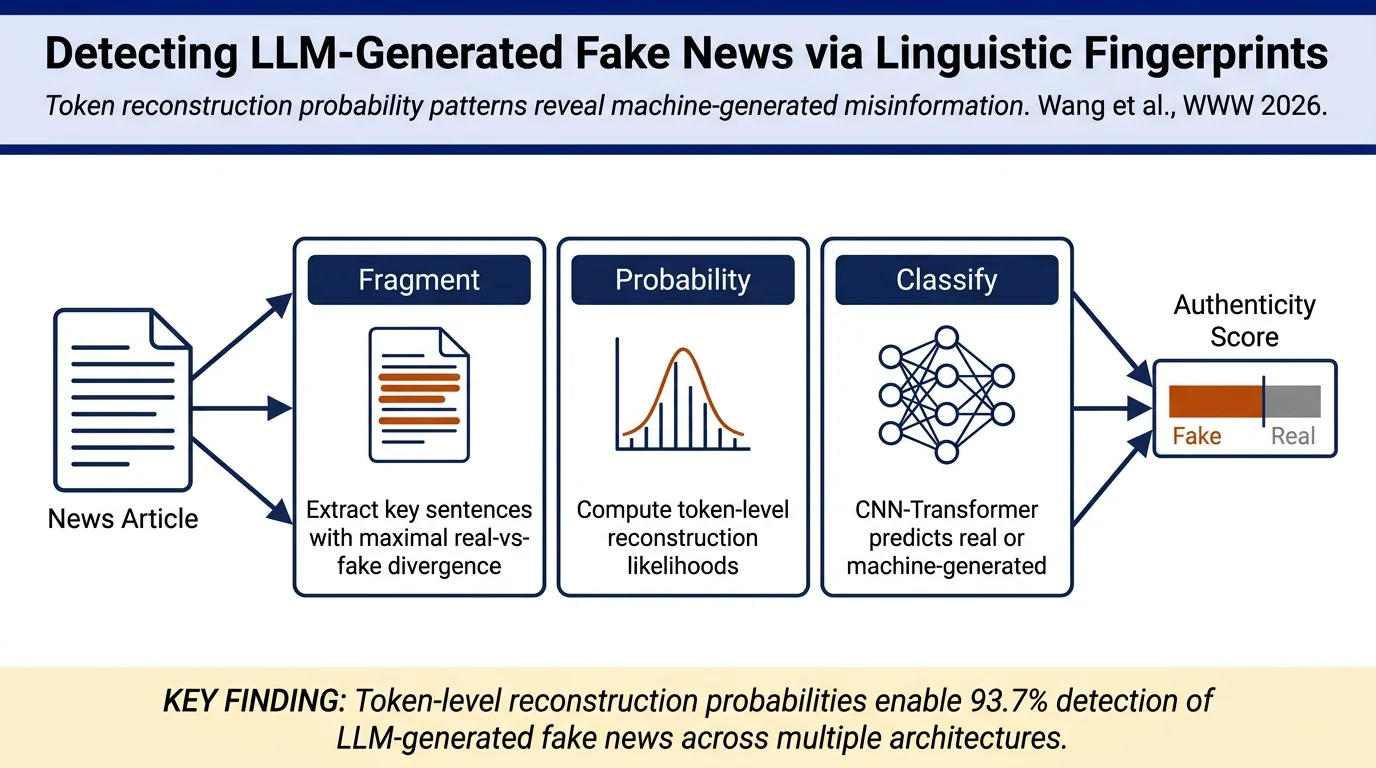
Prompt-Induced Linguistic Fingerprints for LLM-Generated Fake News DetectionLLMs can generate convincing fake news, but malicious prompts induce consistent statistical divergences in token-level reconstruction probabilities. The authors propose LIFE (Linguistic Fingerprints Extraction), which identifies key fragments where real and fake news differ most in their probability signature, achieving 93.7% accuracy on…
 Detection methodsDeepfakes & multimodal
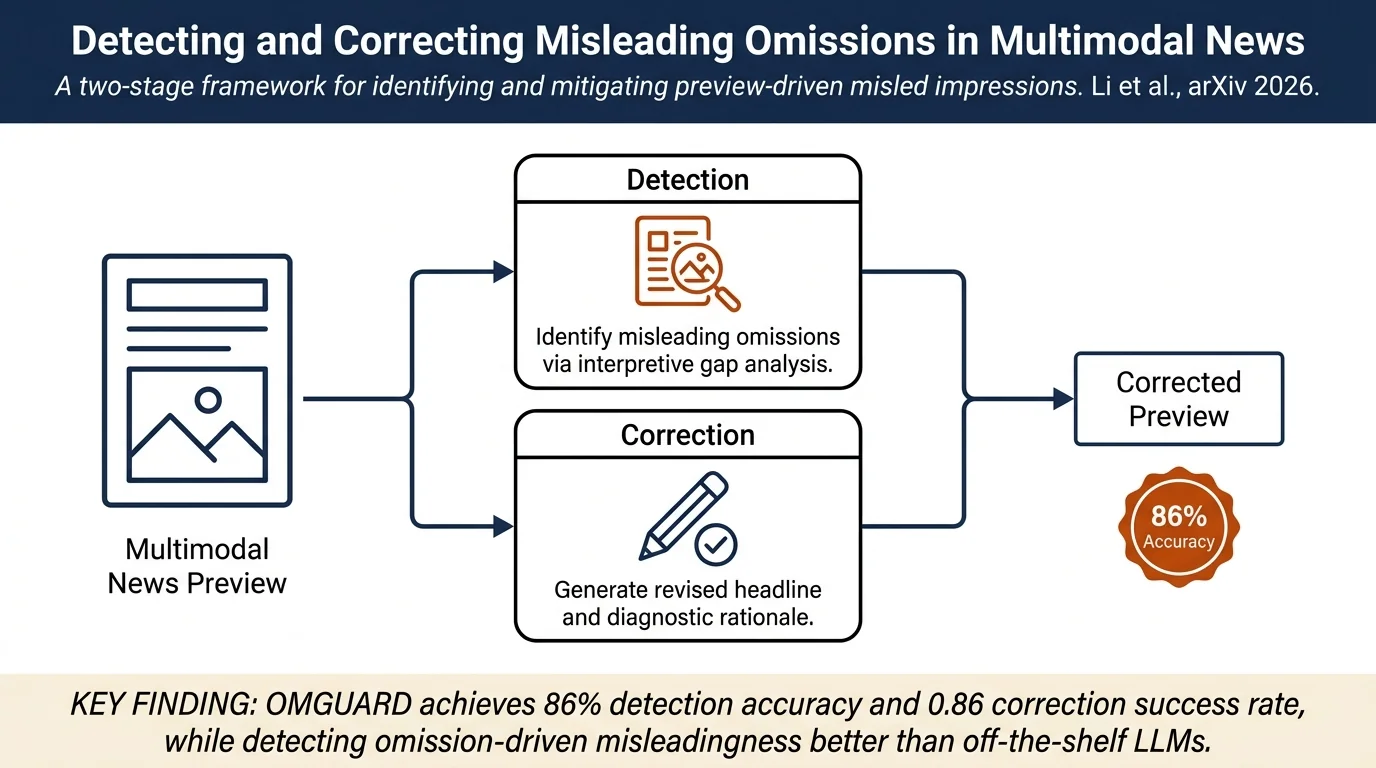
What's Left Unsaid? Detecting and Correcting Misleading Omissions in Multimodal News PreviewsNews previews (headline + image) on social media can mislead readers through selective omission of critical context present in the full article. This paper introduces MM-MISLEADING, a benchmark of 6,000 multimodal news previews annotated for misleading omissions, and proposes OMGUARD, a framework combining interpretation-aware…
 Deepfakes & multimodalDetection methods
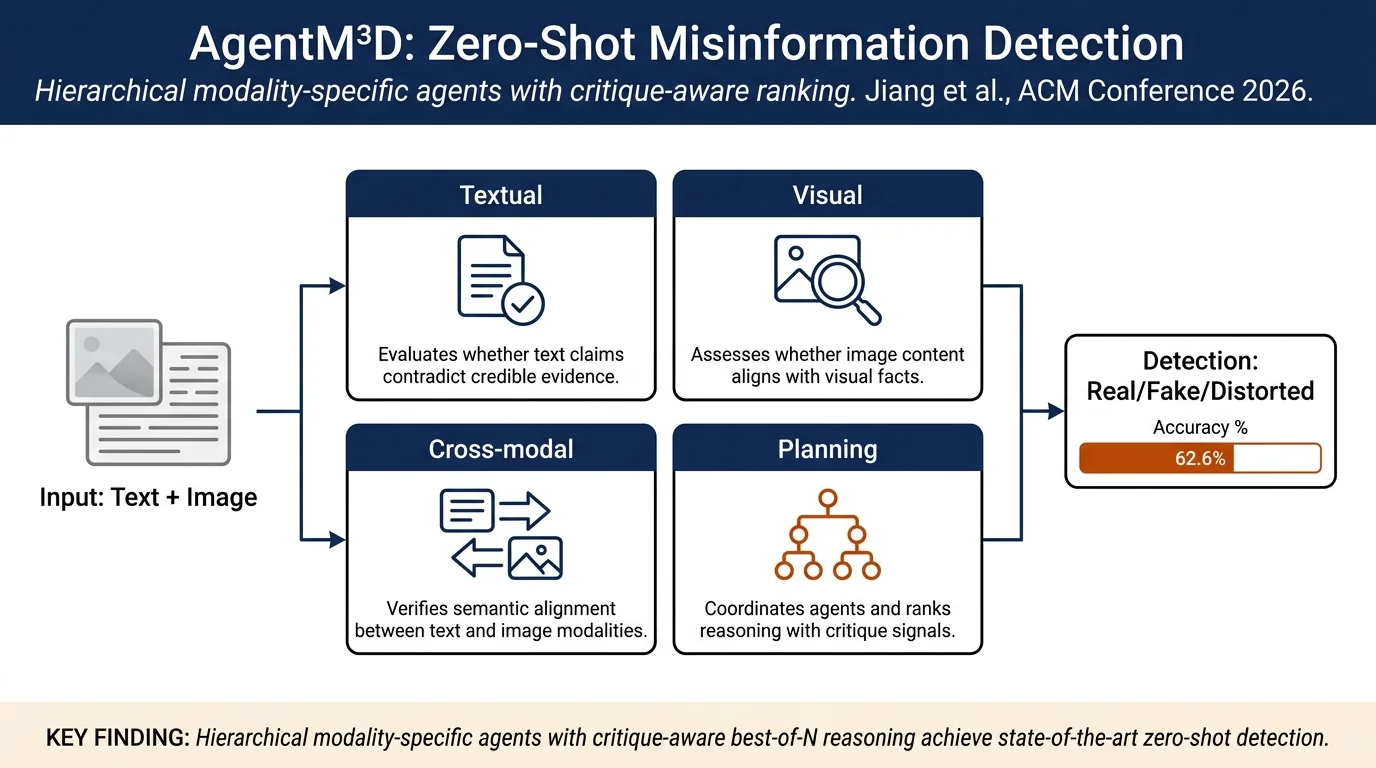
Agentic Mixed-Source Multi-Modal Misinformation Detection with Adaptive Test-Time ScalingVision-language models struggle with mixed-source multi-modal misinformation, where false information combines manipulated images with misleading text or text-image mismatches. This paper proposes AgentM³D, a hierarchical multi-agent framework that decomposes detection into modality-specific agents (textual, visual, cross-modal…
 Deepfakes & multimodalLLMs & generative AI
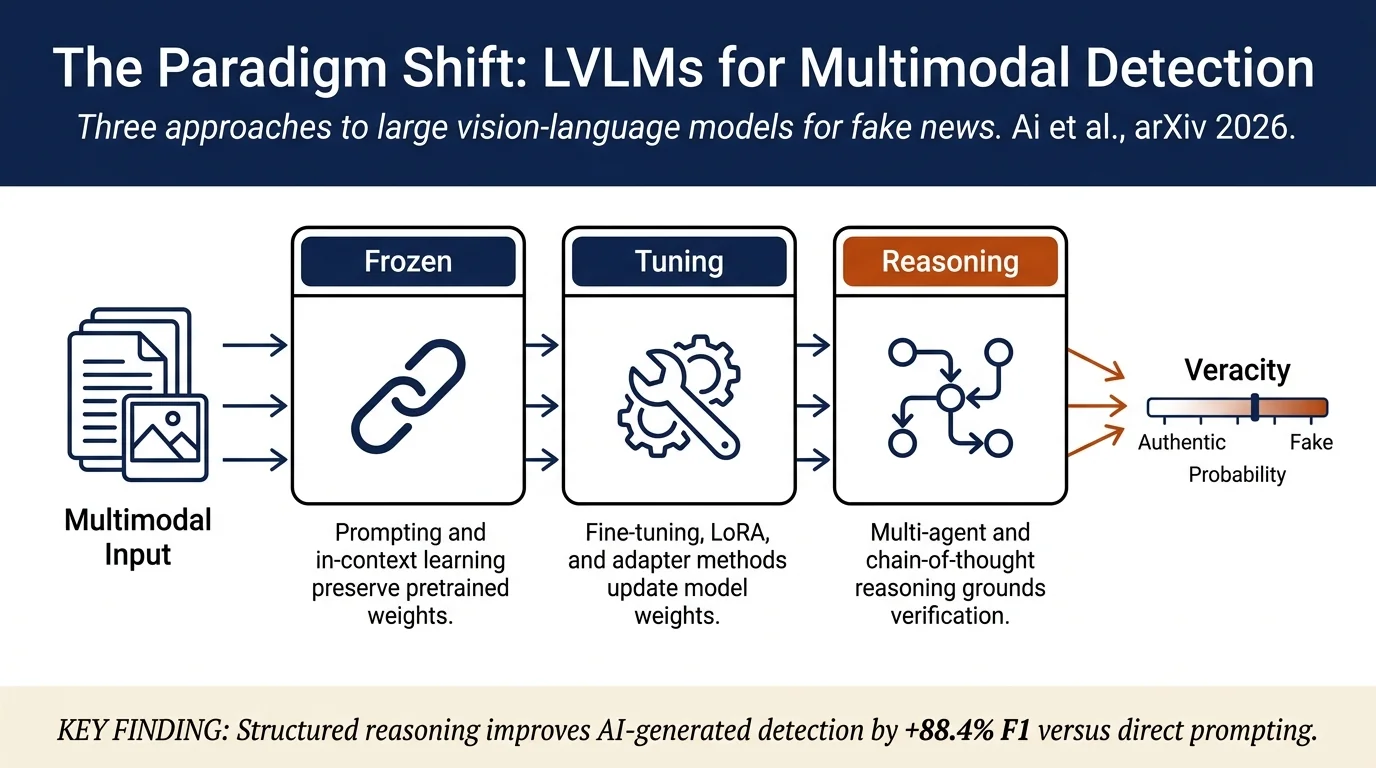
The Paradigm Shift: A Comprehensive Survey on Large Vision Language Models for Multimodal Fake News DetectionThis comprehensive survey systematically reviews the application of Large Vision-Language Models (LVLMs) to multimodal fake news detection (MFND). It proposes a novel three-branch taxonomy categorizing current approaches into parameter-frozen, parameter-tuning, and reasoning paradigms, each addressing different resource constraints and…
 Deepfakes & multimodalLLMs & generative AI
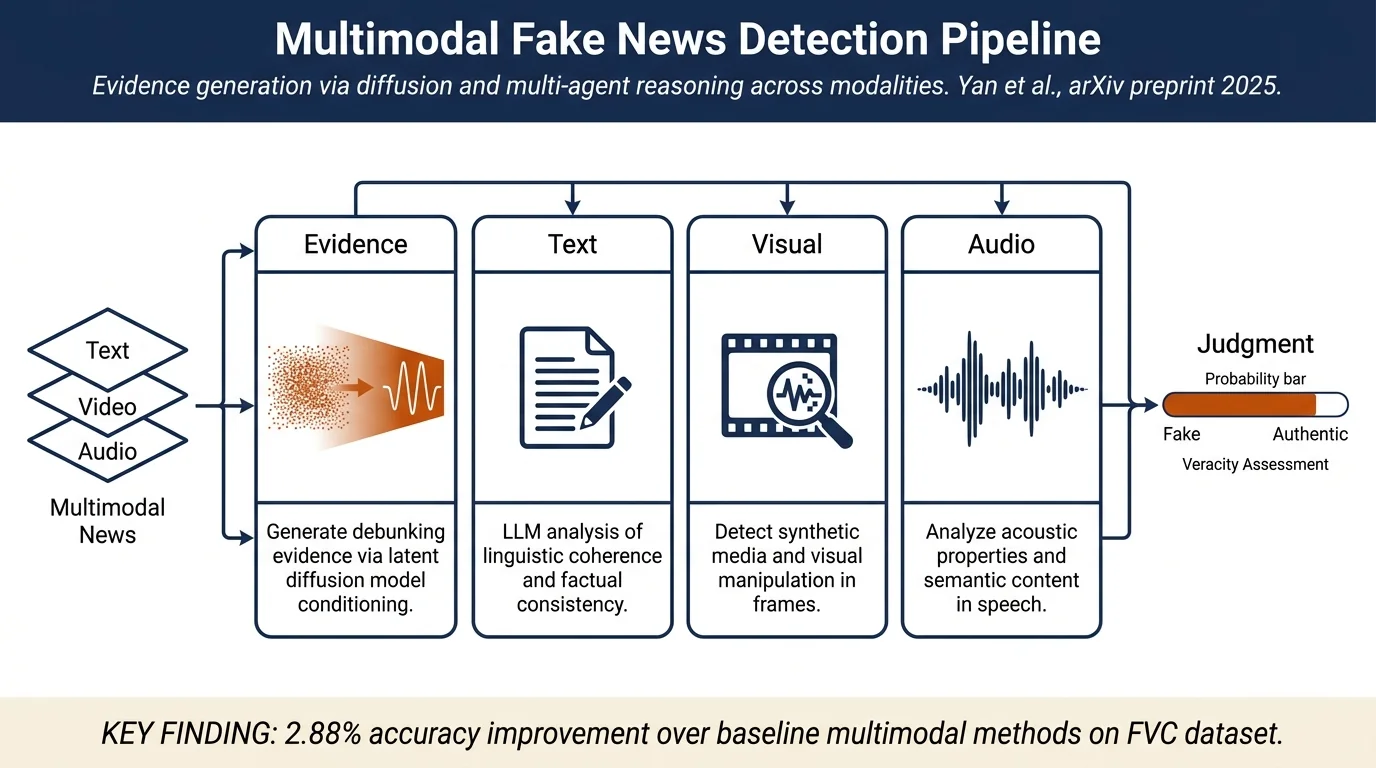
Debunk and Infer: Multimodal Fake News Detection via Diffusion-Generated Evidence and LLM ReasoningThis paper introduces DIFND, a framework for multimodal fake news detection that generates refuting/authenticating evidence via diffusion models and performs reasoning over multimodal content using large language models (LLMs). The approach uses a chain-of-debunk strategy where multiple MLLMs act as collaborative agents to assess news…
 Deepfakes & multimodalDatasets & evaluation
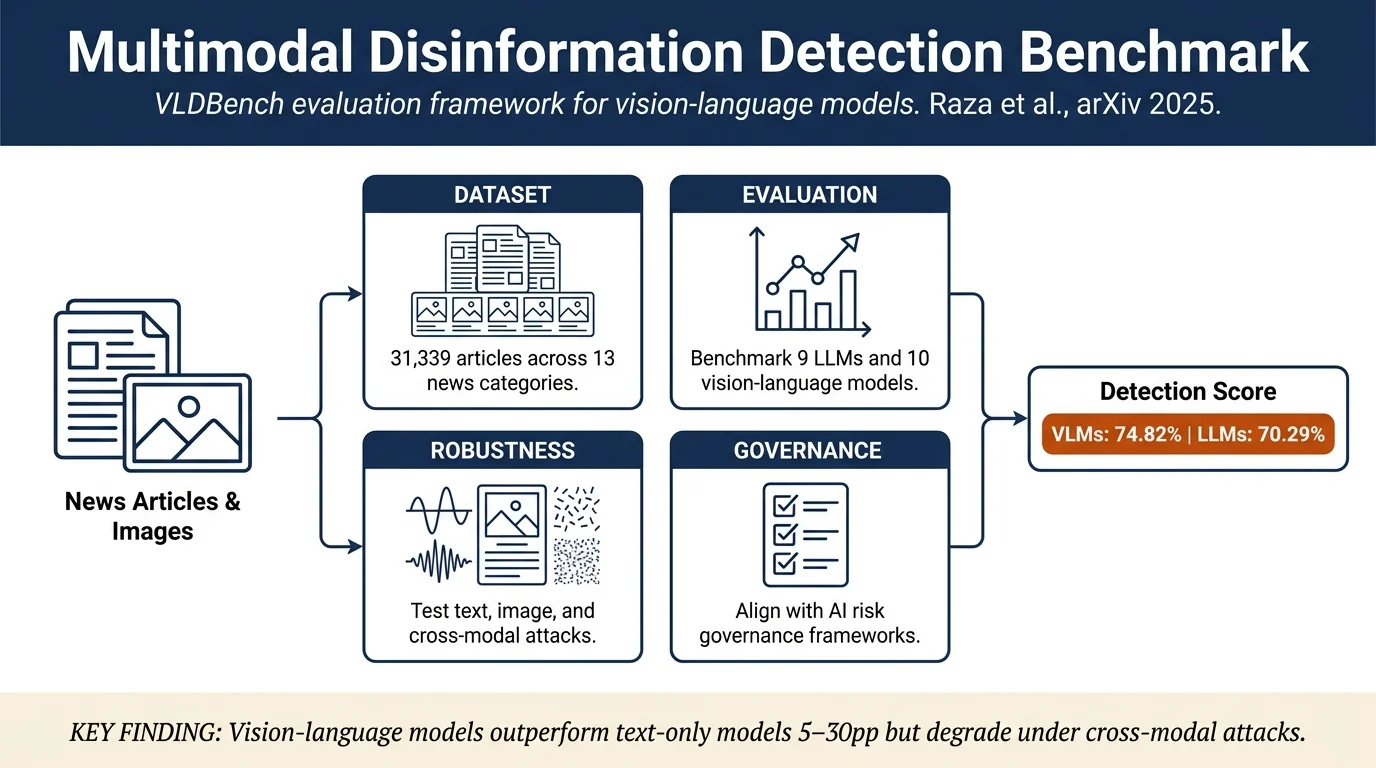
VLDBench: Evaluating Multimodal Disinformation with Regulatory AlignmentVLDBench is the first large-scale human-verified benchmark for multimodal disinformation detection, comprising 31,339 news articles paired with images across 13 topical categories. Evaluation of 9 LLMs and 10 VLMs shows vision-language models substantially outperform text-only baselines (e.g., LLaMA-3.2-11B-Vision: 74.82% accuracy), but…
 LLMs & generative AIDetection methods
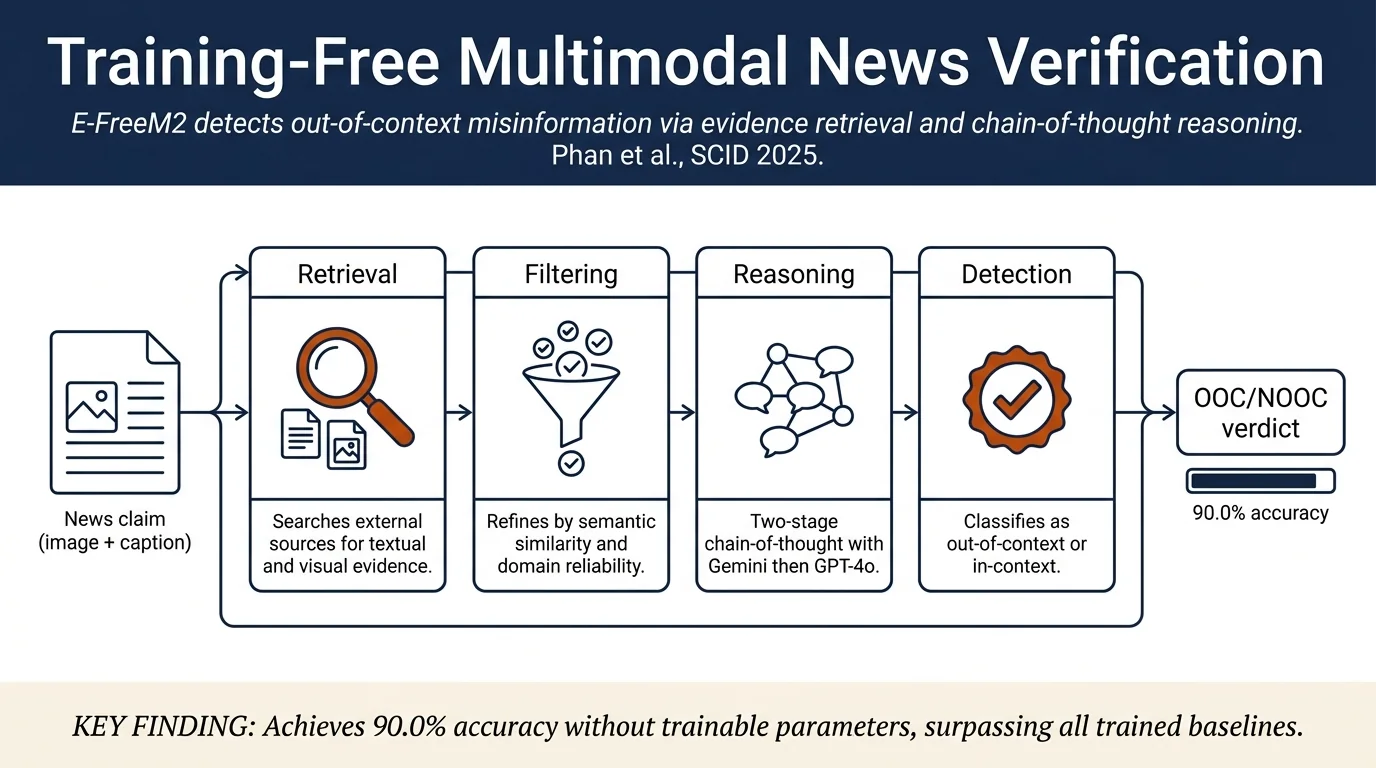
E-FreeM2: Efficient Training-Free Multi-Scale and Cross-Modal News Verification via MLLMsE-FreeM2 is a training-free, retrieval-based multimodal system for out-of-context (OOC) misinformation detection that leverages pretrained vision-language models (MLLMs) and two-stage chain-of-thought reasoning. By dynamically retrieving cross-modal evidence and ranking via visual similarity, the method achieves 90.0% overall accuracy on…
 Deepfakes & multimodalLLMs & generative AI
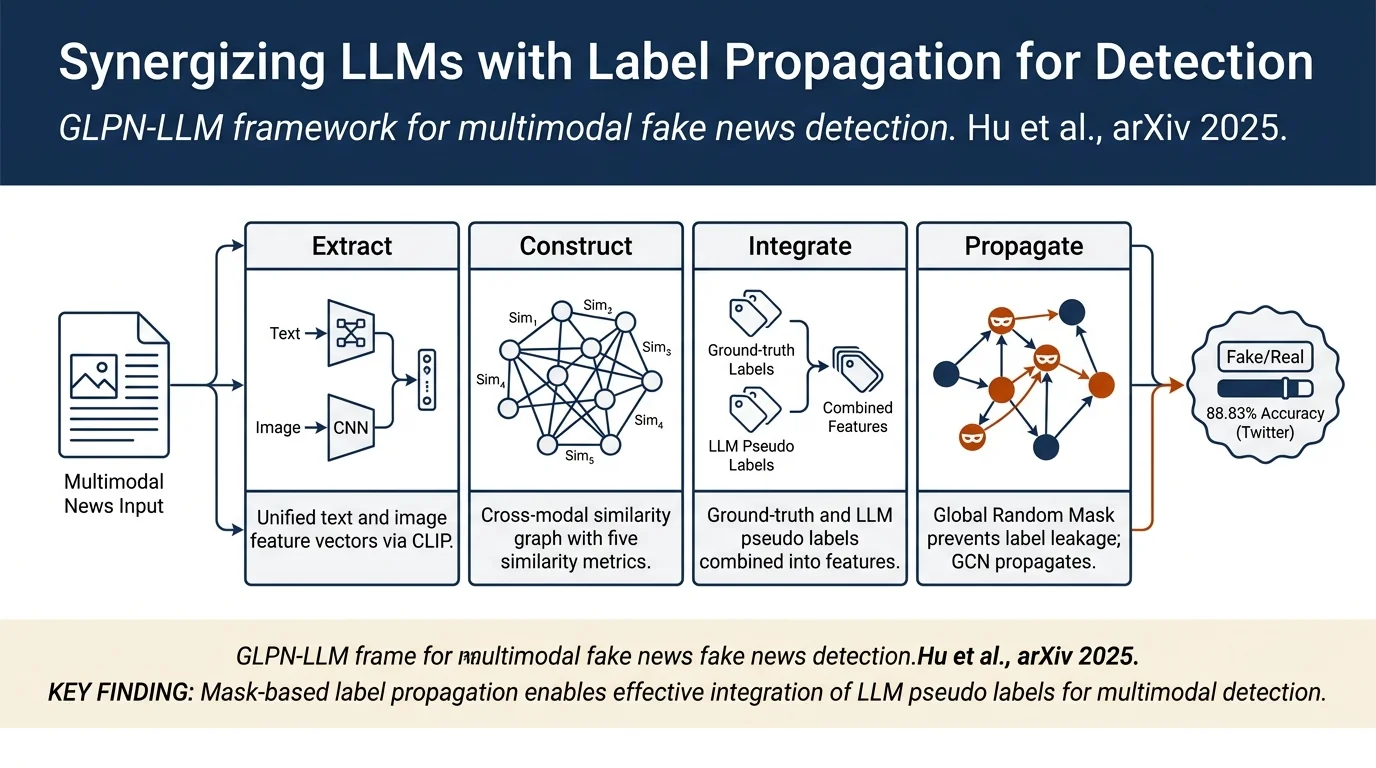
Synergizing LLMs with Global Label Propagation for Multimodal Fake News DetectionThis paper proposes Global Label Propagation Network with LLM-based Pseudo Labeling (GLPN-LLM), a framework for multimodal fake news detection that integrates LLM-generated pseudo labels with label propagation via graph neural networks. A mask-based global label propagation mechanism prevents label leakage during training while enabling…
 Deepfakes & multimodalDetection methods
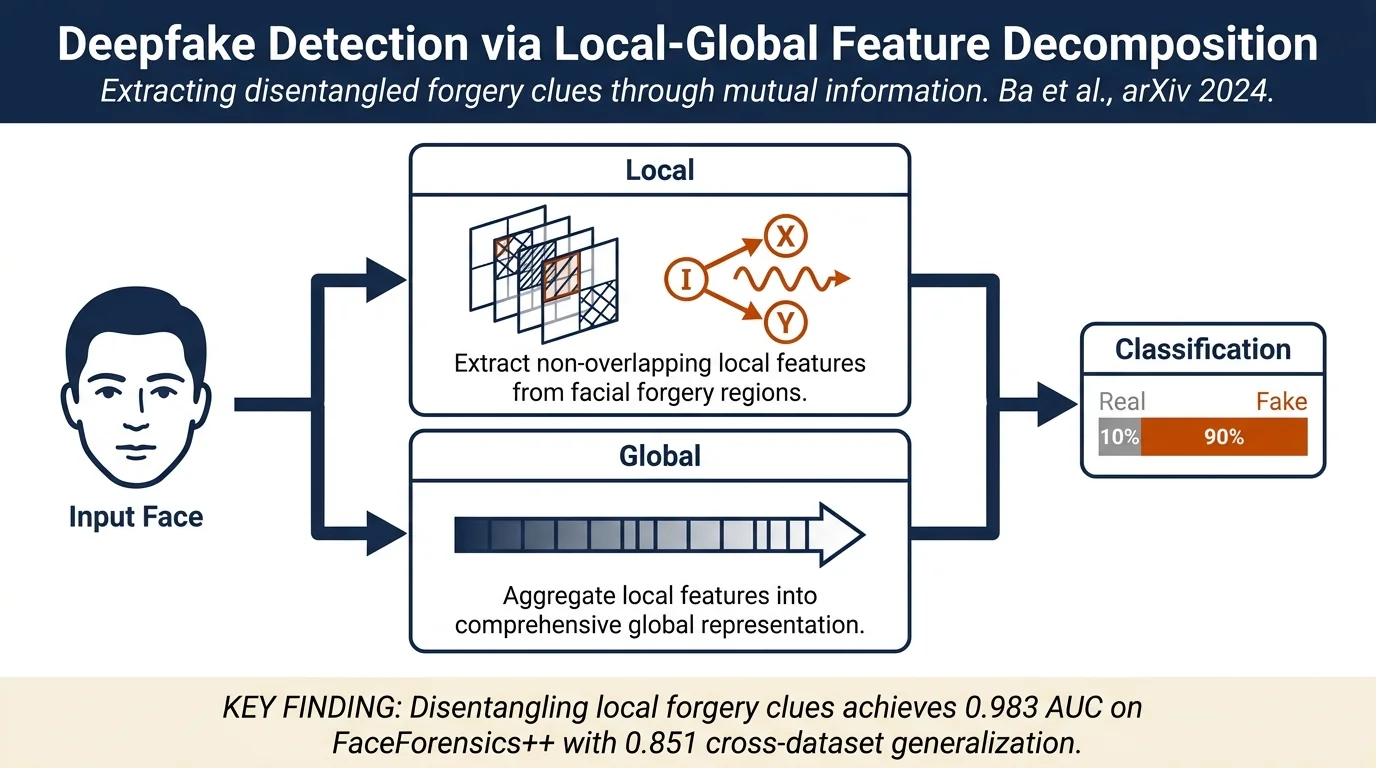
Exposing the Deception: Uncovering More Forgery Clues for Deepfake DetectionThis paper proposes a framework for deepfake detection that extracts both local and global forgery clues by decomposing facial features into disentangled local representations. Using mutual information theory to ensure comprehensive yet non-overlapping feature extraction, the method achieves state-of-the-art results on five benchmark…
 LLMs & generative AIDeepfakes & multimodal
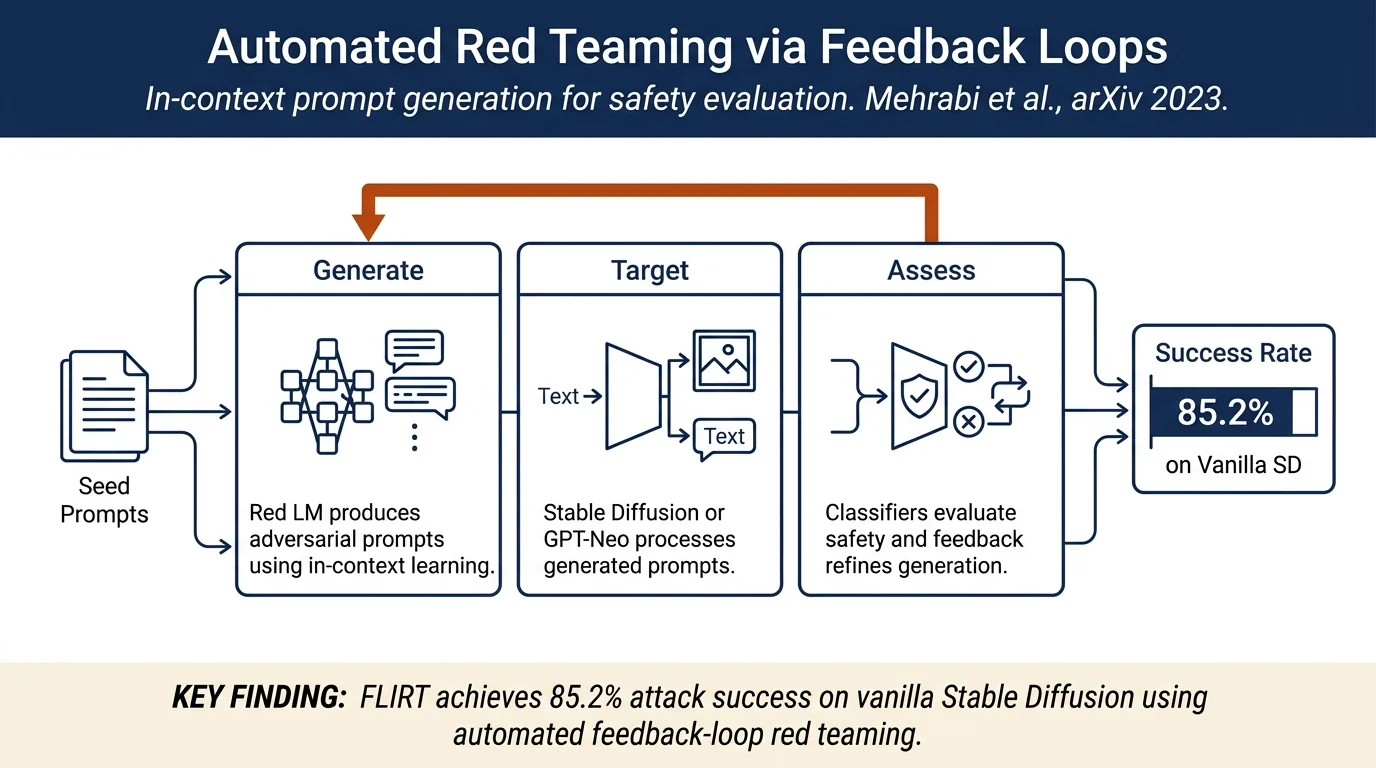
FLIRT: Feedback Loop In-context Red TeamingFLIRT automates red teaming of generative models by using in-context learning to generate adversarial prompts in a feedback loop: a red language model generates candidate prompts, they are evaluated against a target model (e.g., text-to-image or text-to-text), safety classifiers assess the outputs, and results feed back to refine future…