Explore papers
Filter by research area, year and venue. Every filter is in the address bar, so you can share a view as a link.
 LLMs & generative AIDatasets & evaluation
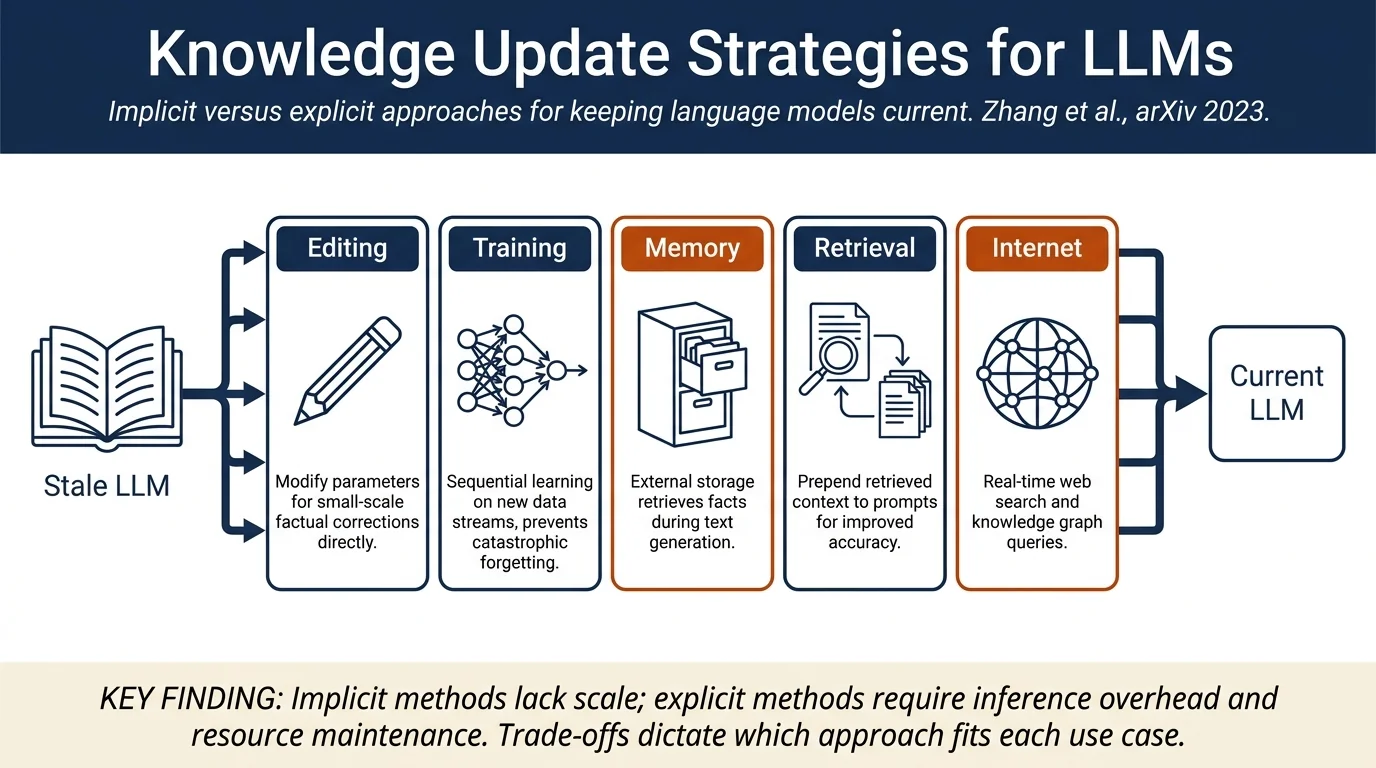
How Do Large Language Models Capture the Ever-changing World Knowledge? A Review of Recent AdvancesThis survey reviews methods for aligning large language models with ever-changing world knowledge without retraining from scratch. The authors systematically categorize approaches as either implicit (modifying LLM parameters directly via knowledge editing or continual learning) or explicit (augmenting LLMs with external resources via…
 LLMs & generative AIFact-checking & verification
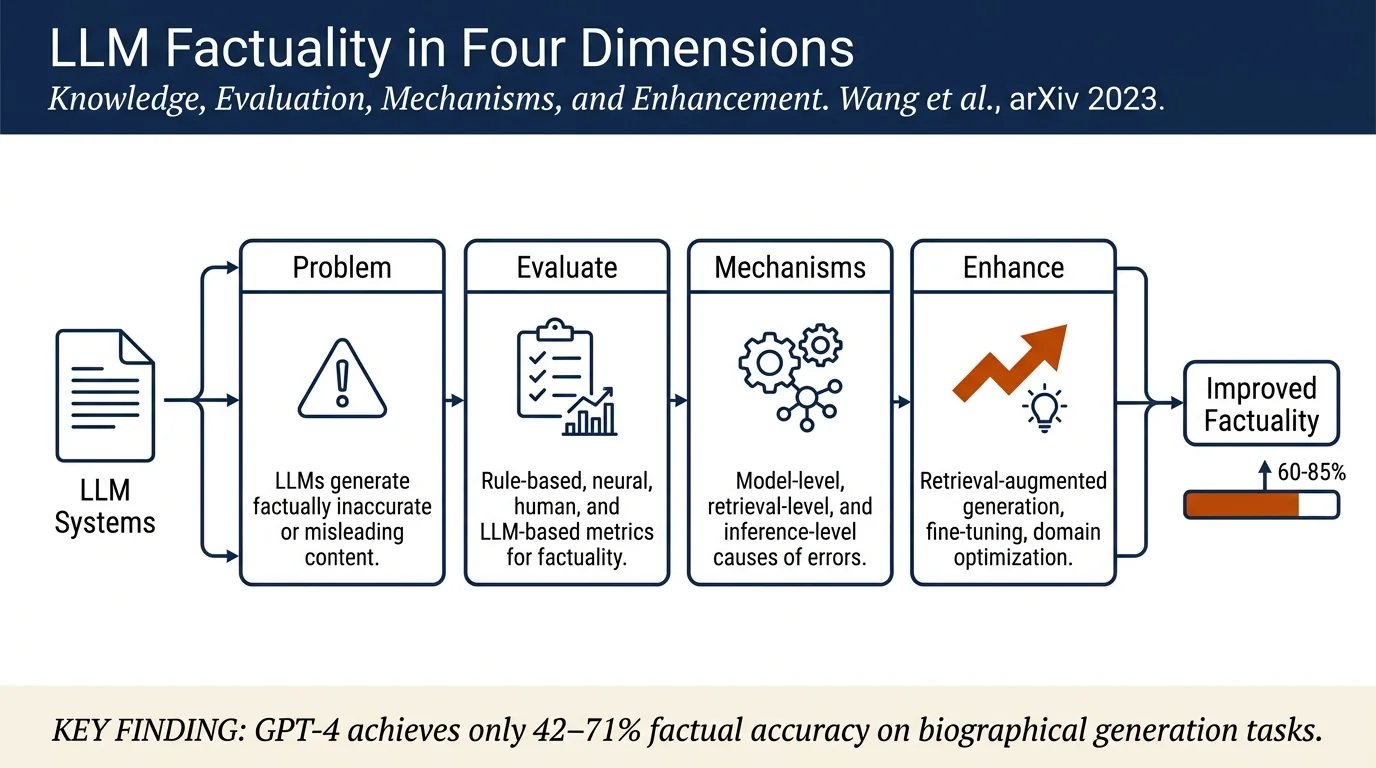
Survey on Factuality in Large Language Models: Knowledge, Retrieval and Domain-SpecificityThis comprehensive survey addresses the critical problem of factuality in large language models, examining how LLMs store and retrieve knowledge, analyzing the mechanisms through which they generate false or misleading content, and reviewing evaluation metrics and enhancement strategies. The paper distinguishes factuality issues from…
 Fact-checking & verificationLLMs & generative AI
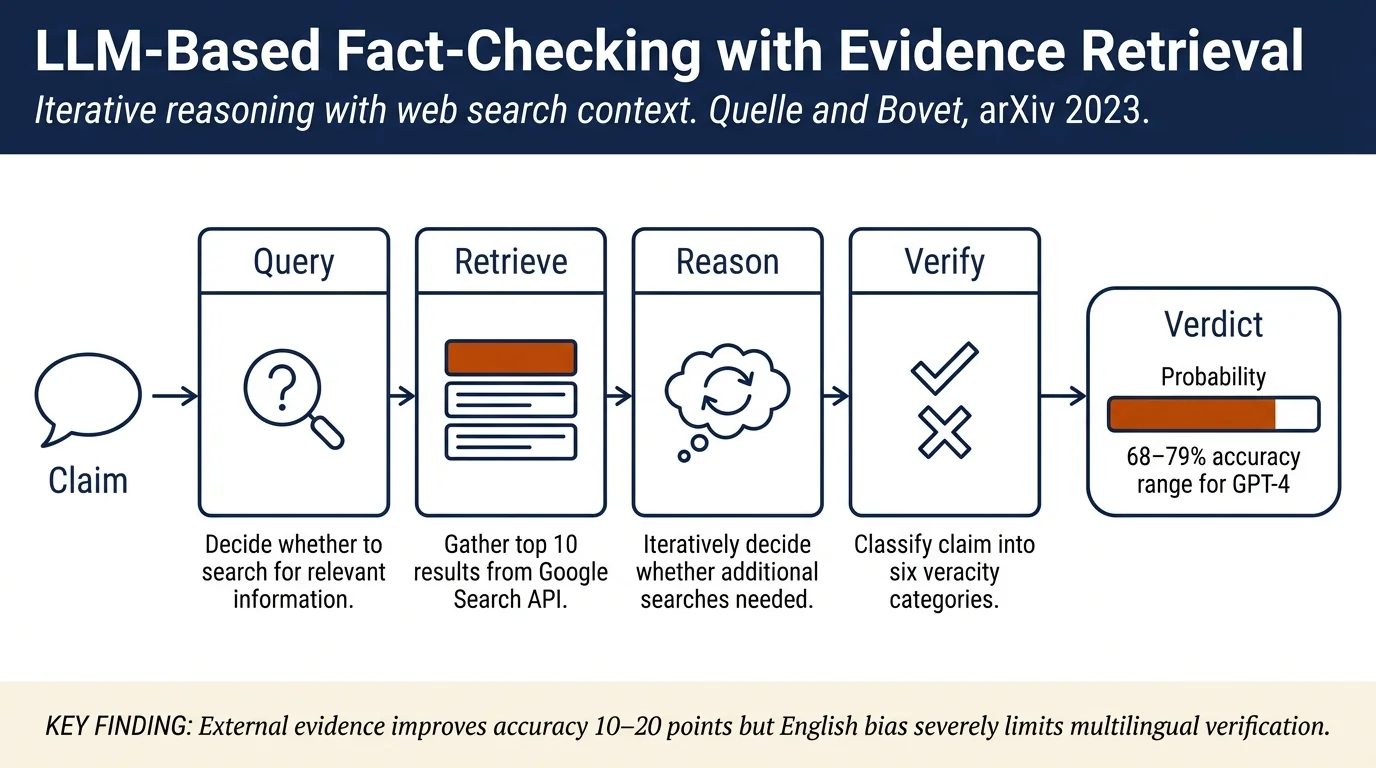
The Perils & Promises of Fact-checking with Large Language ModelsThis paper evaluates GPT-3.5 and GPT-4's ability to fact-check claims across English-only and multilingual datasets, showing GPT-4 substantially outperforms GPT-3.5 but both models show inconsistent accuracy when dealing with ambiguous verdicts. Critically, incorporating contextual information via Google Search significantly improves…